


LakeFlow
Recent items mentioning LakeFlow across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
What is LakeFlow?
Lakeflow is the umbrella name for data engineering on Databricks. It bundles four pieces into one product: Lakeflow Connect for ingesting data from databases, enterprise applications, files, and message buses; Lakeflow pipelines for declarative batch and streaming transformations in SQL and Python; Lakeflow Jobs for orchestration and production monitoring; and Lakeflow Designer, a visual data preparation tool for building transformation workflows using a drag-and-drop canvas or natural language prompts.
The point is consolidation. Ingestion, pipeline logic, and scheduling used to be separate products with separate names, Delta Live Tables and Workflows among them. Lakeflow puts them behind one surface, so the connector that lands your data, the transformations that shape it, and the schedule that runs it live in one place. The pipelines layer is declarative: you state the tables you want, and the engine works out execution order and incremental processing.
Lakeflow reached general availability in June 2025. Its pipeline layer is built on Apache Spark Declarative Pipelines, a framework in the open source Spark project, and runs on the Databricks Runtime while staying interoperable with the open source version. Designer came later and entered Public Preview in April 2026.
What happened to Delta Live Tables (DLT)?
DLT was renamed and became the pipelines layer of Lakeflow. Databricks says the framework is fully backward compatible with existing DLT pipelines, so nothing needs rewriting to adopt the new capabilities.
Is Lakeflow generally available?
Yes. Databricks announced general availability on June 12, 2025, covering Connect, the pipelines layer, and Jobs. Lakeflow Designer arrived later and is in Public Preview.
Is Lakeflow Jobs the same as Databricks Workflows?
Yes, Lakeflow Jobs is the new name for Workflows, the platform's native orchestrator. At GA, Databricks said it was running over 110 million jobs per week. Databricks described the change as evolving Workflows into Lakeflow Jobs and unifying it with the rest of the data engineering stack, not as a migration.
Do Lakeflow pipelines lock me into Databricks?
The framework underneath, Apache Spark Declarative Pipelines, lives in the open source Spark project. Lakeflow pipelines are built on it and stay interoperable with it while running on the Databricks Runtime, so the Databricks-specific part is the managed runtime and platform integration rather than the pipeline model itself.
Sources: Data engineering with Databricks (Lakeflow overview), Databricks docs · Announcing the General Availability of Databricks Lakeflow, Databricks blog · Announcing the Public Preview of Lakeflow Designer, Databricks blog
Lakeflow Designer now supports in-canvas custom operator creation, AI-powered data classification, and specialized components including HTML and Guardrails operators 5. Complementing these design updates, Lakeflow Jobs orchestration offers expanded trigger mechanisms—spanning file arrivals, table updates, model events, and conditional SQL statements 10—alongside practical patterns for alerts, retries 2, and SCD ingestion 3.
Generated daily from the 10 most recent items mentioning LakeFlow. Click any [N] to jump to the source.
 Tutorials
Migrate Databricks classic workloads to serverless with Genie Migrate | Databricks Demo
Genie Migrate is a Databricks tool designed to help users migrate workloads, including notebooks and jobs, from classic clusters to serverless. The tool automatically analyzes code and cluster infrastructure, identifies compatibility issues, and provides suggestions or applies fixes to facilitate the transition to serverless environments.
Lakeflow Jobs: Retries, Timeouts and Alerts That Actually Help
Best Lakeflow ingestion pattern for Full, Append, Replace, SCD Type 1, and SCD Type 2?
I previously worked mostly with custom ingestion frameworks. Now I am starting a new project using Databricks Lakeflow Declarative Pipelines. I need guidance on the recommended pattern for these five write strategies: Full load / overwrite I need truncate-and-load behavior. A direct TRUNCATE did not work. Currently, I use REPLACE WHERE 1 = 1 , but I am concerned about full-table scans and performance on large tables. What is the most efficient approach? Append New batches should only insert rows. No updates, merges, or deletes. Is an Append Flow the recommended solution? Replace by key group The key identifies a group of rows, not one unique row. Each new batch must delete the existing group and insert its new version. Is REPLACE WHERE the correct pattern? SCD Type 1 I am using AUTO CDC for both real CDC feeds and incremental feeds without CDC operation columns. For non-CDC feeds, I use the source file modification timestamp from storage as the sequence key. Is this a reliable and recommended pattern? SCD Type 2 I use the same approach for SCD Type 2: AUTO CDC for both CDC and non-CDC incremental feeds. For non-CDC feeds, the sequence key is the source file modification timestamp from storage. Are there any limitations or better alternatives? What Lakeflow features or APIs would you recommend for each strategy? submitted by /u/warleyco96 [link] [comments]
Databricks Streaming table to Fabric for Gold Lakehouse
Has anyone built an external reference from Lakeflow databricks table to Fabric? The Lakeflow databricks table is sourced from On-prem SQL server and uses change tracking to identify rows that are changed. Databricks writes this out to ADLS Gen 2, which is then shortcut (external referenced) to Fabric. We need the data in near real time. The streaming delta tables in ADLS Gen 2 created by Databricks seem to have additional rows that keep track of deleted rows etc, is there a way to get only the final data after deletes and updates, and secondly, is there a way to get table names without mirroring the databricks unity catalogue? The unity catalogues don't support streaming tables which is what change tracking SQL tables are. Appreciate any help on this or alternative approaches to getting streaming data from Databricks to Fabric. submitted by /u/ObsidianHermit [link] [comments]
 Tutorials
What's New in Lakeflow Designer: AI & Custom Operators
Lakeflow Designer introduces new operators such as HTML and Guardrails, and enhancements like bulk actions and multi-column formulas. It also integrates AI-powered features for data classification and supports custom operator creation within the canvas.
Lakeflow Declarative Pipelines with external: managed tables, or publish step?
I'm working on an Azure Databricks project where we must expose Delta tables through stable ADLS paths so external engines like Snowflake, Trino, and delta-rs apps can read directly from storage. We'd like to use Lakeflow, but managed streaming tables and materialized views live in Unity Catalog managed storage. Can we safely expose their physical paths like regular external Delta tables, or is path-based access unsupported? The alternative seems to be external Delta tables as sinks, but sinks look limited: Python/streaming only, no expectations or Auto CDC directly, and full refresh doesn't clear prior data. For this requirement, what architecture would you recommend: external sinks, a publish step, or something else? submitted by /u/warleyco96 [link] [comments]
Event-Driven Triggers
One of the most important parts of FinOps is to run jobs only when needed. With event-driven triggers like job completion or table triggers, we can run a job as soon as data is available. https://www.sunnydata.ai/blog/lakeflow-jobs-triggers-events-conditions https://medium.com/databrickscommunity/lakeflow-jobs-triggers-06af6feae80c submitted by /u/hubert-dudek [link] [comments]
How are you handling enterprise CDC and file ingestion in Databricks lately? (Lakeflow Connect vs. Custom Spark)
Hey everyone, I’ve been leaning heavily into Databricks Lakeflow Connect and Auto Loader (cloudFiles) recently for managing multi-source ingestion (pulling relational CDC streams like SQL Server alongside high-volume S3 file drops), and I wanted to see how the community is approaching this. Historically, setting up reliable ingestion meant writing custom PySpark streaming jobs, managing checkpoints manually, and dealing with schema evolution headaches when upstream source systems changed unexpectedly. Using Lakeflow Connect combined with Unity Catalog Volumes has noticeably streamlined how raw data hits the Bronze layer, especially for incremental file processing and maintaining clean lineage. I’m curious: Are you guys relying heavily on native Lakeflow/Auto Loader connectors for ingestion, or still building custom Spark/Delta streaming pipelines for specific edge cases? How are you handling schema drift when upstream source tables alter their structure? Any major pain points you've run into with CDC replication in Databricks so far? submitted by /u/SalamanderOpen859 [link] [comments]
Job SQL condition
SQL condition can check whether a trigger should fire. This way, we can avoid unnecessary job runs. https://medium.com/databrickscommunity/lakeflow-jobs-triggers-06af6feae80c https://www.sunnydata.ai/blog/lakeflow-jobs-triggers-events-conditions submitted by /u/hubert-dudek [link] [comments]
 Tutorials
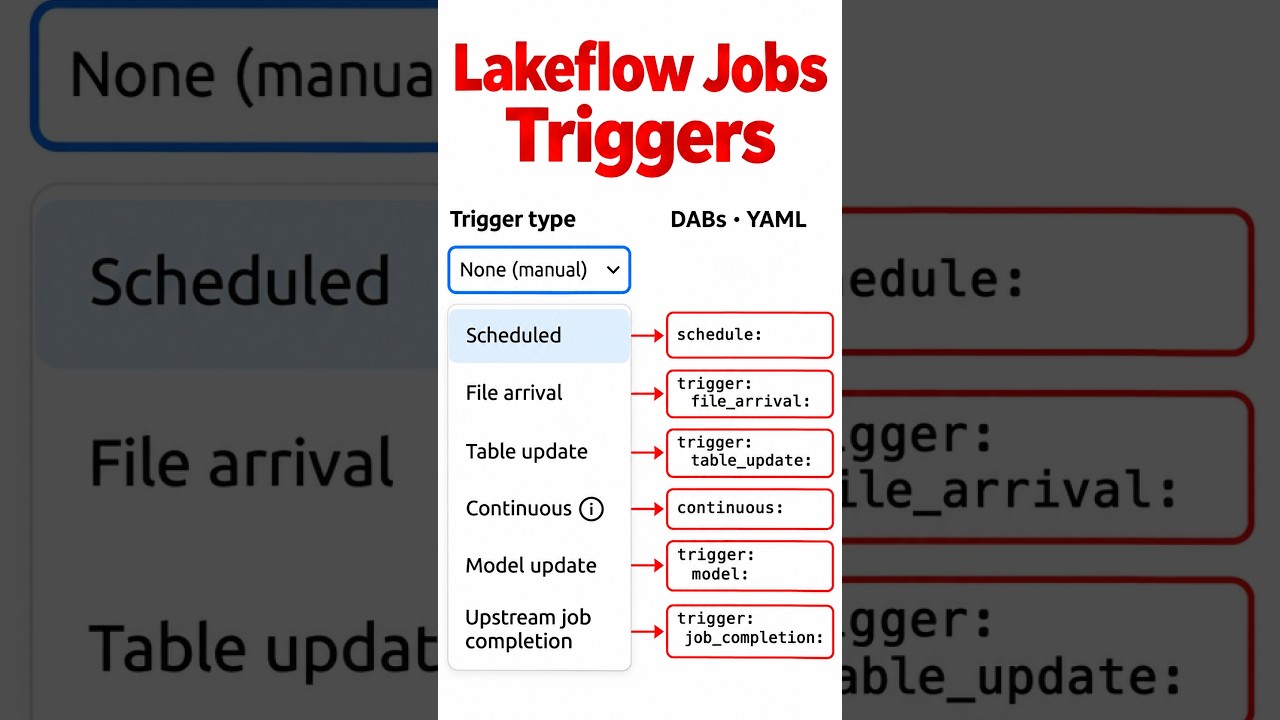
Databricks Lakeflow Jobs Triggers
Databricks Lakeflow Jobs allow users to configure various triggers, such as schedules, continuous runs, file arrivals, and table updates. Additionally, jobs can be triggered by model events, upstream job statuses, and conditional SQL statements.
All Lakeflow Jobs Triggers
It started with scheduled triggers, and now it is starting to get really busy with triggers. I tried to summarize all the triggers available to us today. https://www.sunnydata.ai/blog/lakeflow-jobs-triggers-events-conditions https://medium.com/databrickscommunity/lakeflow-jobs-triggers-06af6feae80c submitted by /u/hubert-dudek [link] [comments]
DQX in Production
Has anyone taken DQX to production? It has been on our backlog for a while and we want to hear people’s experience and lessons from it. Particularly interested if you have integrated it with lakeflow pipelines or implemented contracts with it. submitted by /u/Agitated-Western1788 [link] [comments]
Request for Guidance: Enabling PostgreSQL CDC in Azure Databricks Lakeflow Connect
 News
Genie Code in Lakeflow Jobs: Automate What Happens Next
Genie Code tasks can now run inside a Lakeflow job to automate workflows by executing prompts autonomously. You can add a Genie Code task to a pipeline to investigate data and summarize the results for your team.
Databricks Metric Views are coming back to Power BI! [Private Preview]
First I'd like to give a bit of background because if you feel like you've heard about this feature before, you're right. Previous attempt to bring Metrics Views to PBI was "blocked" when MS removed the required opiton from the connector. In February 2026 - the Power BI Databricks connector introduced Metric View BI Compatibility Mode (Beta). It allowed Power BI to query Unity Catalog Metric Views, with Databricks rewriting the generated SQL to handle measures correctly. In April , Microsoft removed that option from the connector. Reports relying on it stopped working. Now, in November , Databricks has announced a different approach. In new approach Databricks pushes metric view to Power BI semantic model, so ach metric view becomes a table, dimensions become columns, and measures are translated into DAX. You can publish the model from Catalog Explorer or automate it using a Lakeflow Job. There are a few limitations: - Synchronization is one-way, so changes made in Power BI don't flow back to Unity Catalog. - Import mode also changes the security model - imported data is governed by Power BI permissions. For me it's a long awaited feature. I've never been a fan of defining the same business metrics separately in different BI tools. In my opinion metric definitions should live as close to the data as possible, in a shared layer that different reporting tools can use. Connect metric views to Power BI - Azure Databricks | Microsoft Learn https://preview.redd.it/zysb9za0o51i1.png?width=1355&format=png&auto=webp&s=ff3ce75b6bd2c25735f1c368a0721f09cbed8627 submitted by /u/szymon_dybczak [link] [comments]
From enterprise context to action: Genie Agents now analyze more data sources to transform your work
Genie Agents now support analyzing unstructured documents in Unity Catalog volumes with page-level citations in Public Preview, alongside generally available native MCP connectors to read and take action across tools like Jira, Slack, and Google Drive. Teams can also leverage new beta support for OpenSharing and Genie Clean Rooms to securely share governed agents with external partners and customers without exposing the underlying data.
Jobs now check the data before they run (SQL conditions). How would you use it?
We shipped SQL conditions for Lakeflow Job triggers to beta a little while ago, and we want to hear how people would use it plus share a few patterns that work. Docs here: https://docs.databricks.com/aws/en/jobs/trigger-sql-conditions The idea. A trigger tells the job when to run. A SQL condition tells it whether to run. You attach a saved query and a SQL warehouse to a trigger (cron, table, file etc.) and when the trigger fires the query the condition first. https://preview.redd.it/x11wrj7g7u0i1.png?width=1012&format=png&auto=webp&s=9ec41109617eef506116bfc2515bd0d8c525b5f6 There are two modes: Query returns any rows : No rows, no run. Result value changes : the job runs when the return value differs from the last check. Here are a few examples: Freshness plus volume. Today's partition exists and has enough rows, This returns zero rows until the data is ready SELECT 1 FROM main.sales.orders WHERE order_date = current_date() HAVING count(*) > 100 Quality gate. Run only when today's rows have no nulls in a key column. So if there are no bad rows, the job runs SELECT 1 FROM main.sales.orders WHERE order_date = current_date() HAVING count(*) > 0 AND count_if(customer_id IS NULL) = 0 Fan-in. Five upstream feeds write a status row when they finish. Run once all five are done. This replaces the "sentinel table plus a cron that polls it" setup a lot of people run today. Note: if you are watching job completions, then just use job completion triggers! SELECT 1 FROM ops.batch_status WHERE batch_date = current_date() HAVING count_if(status = 'complete') = 5 Watermark advanced. Use "Result value changes" with a one-row, one-column query. The job runs whenever the vendor delivers a new batch. SELECT max(batch_id) FROM main.bronze.vendor_feed Things to know. Each check requires a warehouse and will show up in query history. A check times out at 5 minutes including warehouse startup. Checks run as the job's run-as identity. What is coming next : See why a run did not start. We want each evaluation to show when the query ran, the row count or value it returned, why it did or did not start a run and any error. Parameters. Job parameters inside the condition query, with per-trigger overrides. This is for everyone promoting the same job through dev, staging and prod with bundles, where catalog and schema names change per environment and nobody hand-edits prod. A test button that actually runs the query and shows you the result and whether the job would start right now. Today it only checks that the query exists and has no parameters. Read the condition from a .sql file in the workspace instead of only a saved query, same as SQL tasks already do. A default warehouse so you do not have to pick one every time. Questions for you: What does "ready" mean for your most annoying upstream? Row count, a flag table, a max timestamp, something else? Which of the upcoming items would you use first, and what did I miss? Try it out on Genie code too! Give genie a prompt and see if it picks up your intent as a sql condition. submitted by /u/saad-the-engineer [link] [comments]
 News
Serve Lakehouse Data to Your App with Lakebase Synced Tables
Lakebase synced tables allow you to effortlessly bring Delta tables from your lakehouse into your app's PostgreSQL database. The video demonstrates how to create a continuous sync pipeline and shows that data updates propagate from the lakehouse to the application within seconds.
Lakeflow Jobs is adding date math inside parameters (Beta)
Lakeflow Jobs is adding Math in Parameters . You apply a single + or - duration offset to a date reference inline (where you already write the reference.) When using dynamic references {{job.start_time.iso_date}} you may want to reference yesterday or the hour before. Previously you would need to do this ina notebook or a sql query: {{(job.start_time - 6.hours).iso_date}} -> 2026-09-21 {{(job.start_time - 3.hours).iso_date}} -> 2026-09-22 {{(job.start_time - 1.hour).iso_datetime}} -> 2026-09-22T03:00:00 What's available: job.start_time, job.trigger.time , table update commit timestamps and backfill (only in the backfill modal) Units : years, months, weeks, days, house, minutes. Simgular and Plural so 1.day and 2.days both work You can use these anywhere references work today (job/task parameters, run-now overrides etc.) How do you use math with parameters today? Would love your feedback! submitted by /u/saad-the-engineer [link] [comments]
Lakeflow Connect (Oracle): backfill a single new column without a full refresh of the table
How much "ZeroOps" are you actually seeing in Databricks lately? (Serverless, DLT, Unity Catalog)
Hey everyone, I’ve been looking into the push toward "ZeroOps" within the Databricks ecosystem—specifically leaning heavily into serverless compute, Unity Catalog automation, and declarative tools like DLT/Lakeflow to reduce infrastructure maintenance. Marketing terms aside, I'm curious how much of this is translating to reality in production environments. For those of you managing large Databricks workspaces: Have you fully transitioned to serverless compute (SQL and notebooks), or are you still tied to classic clusters for specific workloads? How much time has Unity Catalog actually saved your team regarding access control and data governance overhead? Where does the "ZeroOps" promise break down for you in day-to-day operations? submitted by /u/SalamanderOpen859 [link] [comments]
Has anyone built production pipelines with Databricks Lakeflow Designer yet? Initial thoughts?
Hey everyone, I’ve been exploring Databricks Lakeflow Designer recently and wanted to see how the community feels about it. For context, it’s Databricks’ new visual, low-code authoring tool built on top of Delta Live Tables (DLT) for building ingestion and transformation pipelines. Historically, I’ve always written DLT pipelines purely in Python or SQL via notebooks or Git folders. When I first saw a visual designer, I was a bit skeptical (usually worried about "black box" code or messy JSON metadata under the hood). However, seeing that it actually compiles down to standard DLT/Spark and integrates natively with Unity Catalog lineage is pretty slick. I’m curious: Are you guys using Lakeflow Designer for production workloads, or keeping it strictly for quick ingestion and prototyping? How does it handle complex CI/CD workflows compared to traditional repo-based DLT code? Any gotchas or limitations you've run into with it so far? submitted by /u/SalamanderOpen859 [link] [comments]
Lakeflow Connect CDC: Data freshness indicator
Hi Reddit, I'm happy to share a new "small but mighty" feature for Lakeflow Connect CDC (Change Data Capture) pipelines: a data freshness indicator. For a long time, "How far behind is my table?" has been one of the most common questions. Now you can answer it directly in the UI. Data freshness = current time − latest ingested source commit time e.g, 3m 21s means the newest change in the table was committed on the source 3 minutes and 21 seconds ago. https://preview.redd.it/y69f25zw1a0i1.png?width=2016&format=png&auto=webp&s=092b2a27159077b678b01f7719b932aa450d1d0b submitted by /u/inkypinky [link] [comments]
[Beta] OneDrive connector in Lakeflow Connect now available!
Hey r/databricks , The Lakeflow Connect connector for Microsoft OneDrive (for business) is now available in Beta . You can ingest structured and unstructured files from a user's "My files" drive into Delta tables for analytics and AI workloads. Managed pipeline authoring is available through the Lakeflow Pipelines API or Declarative Automation Bundles (DABs) . UI-based pipeline authoring is not supported at this time, but will be available soon! Managed pipelines support incremental ingestion, automated retries, Unity Catalog governance, schema evolution for supported formats, and OneDrive-specific and standard file metadata. For direct control over ingestion logic, you can use the Spark + SQL APIs directly: spark.read , Auto Loader, read_files , or COPY INTO pointed at OneDrive URLs. Common workloads Loading Excel, CSV, JSON, XML, Parquet, Avro, and ORC files into Delta tables. Ingesting PDFs, Word documents, PowerPoint files, and images. Parsing documents with ai_parse_document for extraction, search, and agent workloads. Capturing file metadata without loading file contents. Examples using the Spark + SQL APIs Read an Excel range from OneDrive with spark.read : excel_df = (spark.read .format("excel") .option("databricks.connection", "my_onedrive_conn") .option("headerRows", 1) .option("dataAddress", "Sheet1!A1:M20") .load("https://mytenant-my.sharepoint.com/personal/user_mytenant_onmicrosoft_com/Documents/Report.xlsx")) Incrementally ingest PDFs and Word documents, then parse them with ai_parse_document: CREATE OR REFRESH STREAMING TABLE onedrive_documents_parsed AS SELECT *, ai_parse_document(content, map('version', '2.0')) AS parsed_content FROM STREAM onedrive_documents; CREATE OR REFRESH STREAMING TABLE onedrive_documents AS SELECT * FROM STREAM read_files( "https://mytenant-my.sharepoint.com/personal/user_mytenant_onmicrosoft_com/Documents", `databricks.connection` => "my_onedrive_conn", format => "binaryFile", pathGlobFilter => "*.{pdf,docx}"); Try the managed connector Ask a workspace admin to open Previews and enable Lakeflow Connect for OneDrive For Business . Create a Unity Catalog connection to OneDrive . Create a managed pipeline using Declarative Automation Bundles or the Lakeflow Pipelines API . The setup guide includes bundle YAML and an API example notebook . Schedule ingestion with Lakeflow Jobs. For DABs, define the scheduled job in the bundle. Current Beta scope The connector reads from a user's OneDrive for Business "My files" drive. For SharePoint sites, team sites, and shared document libraries, use the SharePoint connector . The connection authenticates as the signed-in Microsoft account and can ingest files that account can access. Managed ingestion requires Unity Catalog, Serverless compute, Databricks Runtime 19 or above, and the PREVIEW pipeline channel. DABs require Databricks CLI version 1.23.0 or above . Resources OneDrive managed connector documentation Managed pipeline setup: DABs and API examples Spark + SQL APIs and examples OneDrive connector limitations Community blog and video tutorial: From PDF to insights Data + AI Summit session: Intelligent Document Processing with Lakeflow If you try the Beta, please provide us your feedback! submitted by /u/BricksterJ [link] [comments]
Lakeflow connect - Oracle
Is anyone here using Lakeflow Connect for Oracle Database? I'm considering moving from Fivetran to Lakeflow Connect and would love to hear about your real-world experiences. A few questions: Ingestion frequency: How often do you run the ingestion? Is it continuously running because of CDC, or do you use scheduled/batch ingestion (is it supported? last time I tested i had two pipelines running one 24/7 to capture cdc and on to load. Last one was possible to schedule)? Stability and maturity: Lakeflow Connect for Oracle is still marked as Beta. Have you experienced any issues, limitations, or reliability problems in production? Cost: This is probably the most important question. What does the ingestion actually cost you? It would be great if you could share some context: Approximate size of your Oracle database / amount of data ingested. Average number of rows ingested per day. Estimated monthly ingestion cost. Fivetran vs. Lakeflow Connect: For those who have made the switch, was it worth it? How does Lakeflow Connect compare to Fivetran in terms of cost, reliability, performance, and overall quality? I'd especially appreciate feedback from anyone running this in a production environment. Thanks in advance! submitted by /u/9gg6 [link] [comments]
Schema evolution: new NOT NULL column fails on existing Silver data (Lakeflow Connect source)
Doing Data Prep on Databricks without Code (Lakeflow Designer Demo)
Jason from Databricks' product team joined me to demo how you can prep data on Databricks without code, using UI-based controls and/or AI inside of Lakeflow, similarly to how you would on Alteryx, KNIME, etc. As a long time fan of making Databricks accessible to everyone, I love how it is easier and easier for business users with limited technical background to use many of Databricks' capabilities. You now have AI/BI Dashboards, Genie One, Genie Agents, Row Zero (spreadsheet acquisition), and Lakeflow Designer. I also personally saw the super early drafts of Lakeflow Designer back when it was still in ideation stage, so love to see where it is at today. The demo itself combines customer orders with inventory data, calculates projected inventory, flags low stock with guardrails, and emails the results. Hope you enjoy it! Some quick answers taken from the questions on the video: What is Databricks Lakeflow Designer? Databricks Lakeflow Designer is a visual, no-code tool for data preparation and workflow automation. Users build transformations with visual operators and natural-language prompts. Who is Lakeflow Designer designed for? Lakeflow Designer is designed for analysts and business users who want to prepare data without writing code. Examples discussed include consulting, financial services, operations, and logistics. How much does Lakeflow Designer cost? Pricing is based primarily on compute/AI consumption, with no per-user licensing fee for Lakeflow Designer. Can you export Lakeflow Designer’s generated code? Yes. Lakeflow Designer’s generated PySpark code can be exported as a notebook. Note: I am a Databricks MVP, work for a consulting company that partners with Databricks, etc. Still, I have full editorial rights on what I say/do. Always try things out yourself! Also note: The Q & A highlights above were created using AI based on the video's transcript. Ultimately, this is a big win for enterprise customers wanting to make the most out of the many capabilities Databricks offers, whether they know how to code or not, and whether they want to use AI or not! submitted by /u/JosueBogran [link] [comments]
 News
Why the Creator of Delta Lake Says: Stop Writing ETL
Spark declarative pipelines, or SDP, allow engineers to define what data tables and transformations should exist rather than manually scripting how to execute them, letting the system handle the underlying orchestration, incremental updates, and error handling. Michael Armbrust and Alexandra Chashchina explain how SDP simplifies data pipelines across various workloads, improves cost efficiency, and reduces manual intervention compared to traditional Spark and Delta Live Tables approaches.
 News
DataBuddy By Tencent Cloud
Tencent Cloud DataBuddy is an agentic platform designed to automate and manage data engineering, governance, and analysis workflows within e-commerce operations. The platform enables users to execute complex tasks from data ingestion to trend analysis while maintaining human oversight at critical approval checkpoints.
Lakeflow Expectations: Dropping Bad Rows Can Hide Real Sales
 Tutorials
How To Detect Telecom Fraud in Real Time with an AI Fraud Analyst Coworker | Databricks Demo
The video demonstrates a real-time telecom fraud detection platform built on Databricks that unifies data infrastructure, governance, and AI agents. It showcases executive, management, and analyst views to monitor fraud metrics, forecast case volume, and investigate high-risk transactions.
Lakeflow Connect – Hard Deletion Sync: GA Timeline and Production Readiness
Data Ingestion Lakeflow UI Bug - Does not allow to create streaming table with BINARY data type
Databricks now supports job completion trigger
Hi, Recently a pretty useful feature appeared on Lakeflow Jobs. It lets you trigger a downstream job when upstream one completes. The jobs can even be in different workspace, as long as they share the same UC metastore. You can configure which upstream run result should trigger the job. This lets us build different workflows based on upstream job outcome. Depending on the outcome, you might want to trigger different jobs: Success: Run data quality checks or refresh reporting tables after the upstream ETL job succeeds. Failure: Trigger a recovery workflow or cleanup job when upstream processing fails. Any completion: Run a finalization job regardless of whether the upstream job succeeded or failed. Trigger jobs when upstream jobs complete | Databricks on Google Cloud https://preview.redd.it/11pqi0pn1dzh1.png?width=1262&format=png&auto=webp&s=bdcb015d6b5816b7c86b27bd7b976f423997e0ad submitted by /u/szymon_dybczak [link] [comments]
New features in Lakeflow Designer this month (October drop)
Hi folks, I'm from the product team working on Lakeflow Designer. Here are some new features released over the last month: 𝗪𝗿𝗶𝘁𝗲 𝗖𝗦𝗩 𝗮𝗻𝗱 𝗘𝘅𝗰𝗲𝗹 𝗳𝗶𝗹𝗲𝘀 𝘁𝗼 𝗚𝗼𝗼𝗴𝗹𝗲 𝗗𝗿𝗶𝘃𝗲 𝗮𝗻𝗱 𝗦𝗵𝗮𝗿𝗲𝗣𝗼𝗶𝗻𝘁 https://preview.redd.it/8qnkb4azubzh1.png?width=3200&format=png&auto=webp&s=6db9b9d75a27e9c7d5f6b4b08db5febe4855a8bb 𝗮𝗶_𝗱𝗲𝗰𝗶𝗱𝗲 𝗶𝗻 𝗔𝗜 𝗙𝘂𝗻𝗰𝘁𝗶𝗼𝗻𝘀: yes/no, choices, or scores from text https://preview.redd.it/vd3oc6m0vbzh1.png?width=2624&format=png&auto=webp&s=052cf654b51b56e74e19d83c6f1ad6539ddbfef1 𝗛𝗧𝗠𝗟 𝗼𝗽𝗲𝗿𝗮𝘁𝗼𝗿: build custom HTML, CSS, and JS reports https://preview.redd.it/t078g6j1vbzh1.png?width=2624&format=png&auto=webp&s=3e62baf8f92dd665d1c1ed77bcd4c9d715b44529 𝗣𝗮𝗿𝘀𝗲 𝗝𝗦𝗢𝗡: turn a JSON column into regular column https://preview.redd.it/8jbwdsx2vbzh1.png?width=3200&format=png&auto=webp&s=130af7d4147bed99e90cd5b168c2243cf6736020 𝗖𝗼𝗹𝗼𝗿-𝗰𝗼𝗱𝗲𝗱 𝗴𝗿𝗼𝘂𝗽𝘀 𝗮𝗻𝗱 𝗻𝗼𝘁𝗲𝘀: keep big canvases readable https://preview.redd.it/xhhb4uf5vbzh1.png?width=3200&format=png&auto=webp&s=98c47fa6087fe99ef293122c868e535cf214b229 𝗠𝘂𝗹𝘁𝗶-𝗰𝗼𝗹𝘂𝗺𝗻 𝗳𝗼𝗿𝗺𝘂𝗹𝗮: write one expression, apply it to many columns https://preview.redd.it/mnes5di6vbzh1.png?width=3200&format=png&auto=webp&s=511c7132d5a9cc68a654fb27b36b3e36947b45fd 𝗕𝘂𝗹𝗸 𝗿𝗲𝗻𝗮𝗺𝗲 𝗰𝗼𝗹𝘂𝗺𝗻𝘀: prefix, suffix, case, or find-and-replace https://preview.redd.it/cbp9qao7vbzh1.png?width=3200&format=png&auto=webp&s=7a67a55442b4c1c65680fded810932f952a7d8aa 𝗥𝘂𝗻 𝘂𝗽 𝘁𝗼 𝗵𝗲𝗿𝗲: run only the steps leading to one operator https://preview.redd.it/g4c5mdk8vbzh1.png?width=3200&format=png&auto=webp&s=eecea78ee543906feb74c40c1ead1d2cd7b1cc2e submitted by /u/zaboca_v [link] [comments]
Databricks and SAP unleash end-to-end data & AI capabilities to level up enterprise AI transformation
Databricks and SAP are expanding their partnership to give customers broader access to SAP application data across cloud and on-premises, speeding time to value for analytics and AI. Genie, Lakeflow, Unity Gateway, and Lakebase now come to SAP Databricks fully integrated with SAP Business Data Cloud, so teams can use the full Data + AI Platform on all their SAP data.
Lakeflow Connect | NetSuite Connector (GA)
Lakeflow Connect's NetSuite connector is now GA! It provides a managed, secure, and native ingestion solution that accesses NetSuite data through the SuiteAnalytics Connect JDBC driver and lands it in Databricks. The connector supports incremental ingestion, SCD Type 2, and automated schema evolution! Try it now: Set up NetSuite as a data source Create a NetSuite connection in Catalog Explorer Create the ingestion pipeline via the UI, a Databricks notebook, or the Databricks CLI submitted by /u/Brickster_S [link] [comments]
Lakeflow Connect | LinkedIn Ads Connector (Beta)
Lakeflow Connect's LinkedIn Ads connector is now available in Beta! It provides a managed, secure, and native ingestion solution for LinkedIn Ads resource tables (ad accounts, campaign groups, campaigns, and creatives), as well as seven pre-built reports covering daily campaign and creative performance plus monthly member demographics. Try it now: Enable the LinkedIn Ads Beta: Workspace admins can enable the Beta via: Settings → Previews → "Lakeflow Connect for LinkedIn Ads" Set up LinkedIn Ads as a data source Create a LinkedIn Ads connection in Catalog Explorer Create the ingestion pipeline via a Databricks notebook or the Databricks CLI submitted by /u/Brickster_S [link] [comments]
Unify your productivity and AI data with Lakeflow Connect
Lakeflow Connect now offers native, fully managed connectors for Atlassian (Jira, Confluence), Microsoft SharePoint, Google Workspace (Drive, Outlook, Gmail), GitHub, and AI providers like OpenAI and Anthropic, with unified governance and no infrastructure to manage. Because both structured and unstructured data land directly in Unity Catalog, teams can power enterprise knowledge bases, AI agents, and developer productivity dashboards without building custom API integrations or pipelines.
 Tutorials
Lakebase Search: Build AI Retrieval for Agents with Lakebase Postgres
Lakebase Postgres introduces lakebase vector and lakebase text extensions to support hybrid search for AI agents. It leverages the Databricks Lakehouse architecture to synchronize and index data for efficient vector and full text search without requiring external databases.
Pipelines Editor - "Run selected code" ignores the pipeline's default catalog/schema, but "Run file" uses them
I know the Databricks SDP crew hangs out here, so I wanted to just surface one inconsistency in the Lakeflow Pipelines Editor that is tripping up our new analysts and request it be reviewed for a possible enhancement. The request is to have "Run selected code" start its session with the pipeline's default catalog and schema, the same way pipeline runs do. If there's a reason it can't, a note in the Query Results panel showing which catalog/schema the query ran against would at least make the behavior visible. As far as I can tell, the editor docs don't mention it either. The editor shows the pipeline's catalog and schema right there, so the natural assumption is that everything on that page uses them. When it doesn't, users conclude the table or pipeline is broken. I know they can use either.... Add USE CATALOG / USE SCHEMA to the selection, or Temporarily hard-code three-part names, which you then must remember to remove before committing (a real risk with bundle-deployed, per-user schemas). ...but that means they're messing with the code, which leads to leaving those bits in the SQL later. Thanks. Otherwise the editor has been great! submitted by /u/lofat [link] [comments]
Beyond the Dashboard: Why AI Data Assistants Fail Without Unity Catalog Governance
For years, the promise of self-service BI has been a moving target. We gave business users drag-and-drop tools, semantic layers, and natural language query bars. Yet, time and again, we hit the same wall: trust. When a business user asks an AI tool, "What was our fleet downtime last quarter?" , the AI is only as good as the underlying data fabric. If your data is trapped in fragmented silos, uncatalogued, and un-governed, conversational AI quickly becomes an expensive generator of confident misinformation. This is where the paradigm is shifting. With the introduction of tools like Databricks Genie , we are moving past rigid dashboards into the era of conversational analytics. But as Solution Architects, our job isn't just to look at the UI layer—we have to look at the spine of the architecture. Here are three architectural realities I’ve learned while implementing modern Lakehouse patterns: 1. AI Without Governance is Just Automated Chaos You cannot point an LLM at a raw storage bucket and expect accurate insights. Genie relies entirely on the metadata, table descriptions, and foreign key relationships defined in Unity Catalog . If your governance layer is messy, your AI's answers will be messy. Unity Catalog isn’t just a security tool anymore; it is the semantic foundation for enterprise AI. 2. The Shift from "Building Pipelines" to "Curating Context" Tools like Lakeflow Connect and automated ingestion frameworks are taking over the heavy lifting of ETL. As data engineers and architects, our value is no longer measured by how many custom Spark scripts we write to move data. Our value is measured by how well we curate the Gold layer —structuring tables, defining clear column descriptions, and setting up quality expectations so that tools like Genie can actually understand the domain context. 3. Real-Time Trust Beats Real-Time Speed In heavy industries—like managing IoT telemetry for gas turbines—getting data in 5 seconds doesn't matter if the data quality is flawed. Integrating Delta Live Tables (DLT) Expectations as a quality firewall before data hits the consumption layer ensures that both human analysts and AI assistants are querying verified, pristine data. The Takeaway Conversational AI and natural language agents like Genie are the future of data consumption. But they are built on a simple architectural truth: Garbage in, hallucination out. If we want business users to trust AI-driven insights, we have to start by modernizing our foundations with robust governance, automated pipelines, and strict data quality gates. Curious to hear from other architects out there: Have you started deploying conversational AI tools to business users yet? What are the biggest governance or data trust hurdles you've had to overcome? submitted by /u/SalamanderOpen859 [link] [comments]
How do you handle CDC from legacy databases into Databricks: Lakeflow Connect, Debezium, or custom Spark jobs?
We’re moving data from an older Oracle database (about 20M rows in the main table, with daily inserts, updates and deletes) and trying to pick the right approach for keeping things in sync. Our constraints: -No timestamp or audit column on the source table -Can’t add triggers or change the source schema -Limited privileges on the source (no LogMiner access right now) What we’ve tried so far is a custom Spark job: we use ORA_ROWSCN to find changed rows, a key anti-join to detect deletes, and then MERGE into the target. It works, but it feels fragile, and the delete detection has to scan all keys every run. For those who’ve done this in production: -Are you using Lakeflow Connect, Debezium + Kafka, or custom Spark/JDBC jobs? -How do you handle deletes when the source has no change tracking? -Was it worth pushing the DBA team for log-based CDC access? -Any lessons on cost, reliability or maintenance? Would love to hear what’s working (or not) for you. submitted by /u/No_Ambition8323 [link] [comments]
Costing of Lakeflow Connect Integrated CDC Pipeline
Hi All, Currently I'm facing the issues in finding the costing of the integrated cdc pipelines, I'm not using serverless compute in pipelines and before 1st Oct in usage system tables we were getting the entries and in usage_metadata column we were getting the dlt_pipeline_id, but after 1st Oct this values is comming as null. Is there any other way to calculate the costing of these pipelines. submitted by /u/Swimming-Regular6674 [link] [comments]
 News
Building Reliable Data Pipelines with Lakeflow on Databricks | Lakeflow Demo
Databricks Lakeflow provides a data intelligence platform for building and managing reliable data pipelines. The demonstration covers creating delta tables, ingesting data from Salesforce using Lakeflow Connect, and using Lakeflow Designer for data transformation and orchestration.
Introducing Lakeflow Designer: No‑Code SQL Pipelines in Databricks
Would you trust a pipeline migration that skips reprocessing but keeps the streaming checkpoint?
I'm exploring newer import_checkpoint capability in lakeflow spark declarative pipelines. Suppose we have a production streaming pipeline processing millions of records daily. We want to migrate it into a declarative pipeline without reprocessing old data or losing the streaming state. But what happens if the source schema changes, some records arrive late, or the old checkpoint is no longer compatible with the new pipeline? Would you use checkpoint import in production, or would you prefer a full refresh for safety? What edge cases would you test before making the switch? submitted by /u/No_Ambition8323 [link] [comments]
 Tutorials
Tutorial: Genie for Data Engineers, Data Scientists, and Everybody Else
This tutorial demonstrates how to use Databricks Genie to build a live web app and data pipeline from a 700-million-row IoT dataset. The process covers getting the data from the Databricks Marketplace, running exploratory data analysis, building pipelines and jobs with Genie Code, querying data on mobile, and receiving shared data locally.
Databricks World. I think they forgot the Pirates of Renaming
I really liked the Databricks World map they showed at DAIS, so I decided to make my own version. But I felt like something was missing... The Pirates of Renaming Not long ago, I was trying to figure out the difference between DLT and SDP. But it seems like the last name is Lakeflow Pipelines. What should I add to the map next? submitted by /u/Significant-Guest-14 [link] [comments]
What’s new in Databricks - September 2026?
Databricks shipped the following major GA launches in September 2026: 👉 Spark Declarative Pipelines (SDP): Lakeflow Spark Declarative Pipelines now feature structured maintenance windows for continuous runs, zero-reprocessing migrations (import_checkpoint), multi-source append flows, and explicit cascade deletion (cascade: true) for Unity Catalog tables. 👉Governance and ABAC Security: Metastore-level Attribute-Based Access Control policies and explicit DENY rules are now GA in Unity Catalog, automatically enforcing data protection and access rules across all present and future catalogs. 👉Connectors and Data Applications: Lakeflow Connectors reached GA for Anaplan, Anysphere, and Celigo, while Genie Ones MCP server was officially made generally available for AI assistant workflows. Full article 👉 https://community.databricks.com/t5/product-platform-updates/what-s-new-in-databricks-september-2026/ba-p/173896 submitted by /u/Youssef_Mrini [link] [comments]
How to get the most out of running dbt on Databricks
Consolidating your entire pipeline within a single dbt project on Databricks eliminates fragmented tooling from streaming ingestion through governed metric definitions. This unified approach lets you orchestrate natively using Lakeflow Jobs while enforcing Unity Catalog access rules directly from your dbt project configurations.
Run Lakeflow pipelines as a group: governance win or a way around SP gatekeeping?
As of this month you can set a Lakeflow pipeline’s run-as identity to an account group. Tables the pipeline publishes become group-owned in UC. Two patterns I expect to see: 1. Routing around SP provisioning. In a lot of orgs, creating a service principal is process-locked by a platform or identity team. Tickets, approvals, secret rotation. With run-as group, a team that already has an account group with the right grants can skip all of that. The conversation moves from “who can create an SP” to “can we just use the DE group?”. 2. Lower-maturity teams leapfrogging SPs. Teams still running pipelines as individual users will likely jump straight to groups. That’s better than personal identities, since nothing breaks when someone leaves. But it means they may never adopt SPs at all, and “good enough” becomes the permanent pattern. Questions for the sub: If you run pipelines as SPs today, are you planning to switch any to groups? Platform/admin folks: are you going to restrict this, and how? How are you handling auditability when the identity is a group instead of a single SP? Is group run-as a legit middle step for teams coming off user identities, or a dead end? My take: SPs still belong in prod. But I’d bet most orgs end up with group run-as spreading through both of these doors, and won’t notice until an audit asks who ran what. submitted by /u/OkImprovement7010 [link] [comments]
 News
Databricks Breaking News: Lakeflow Jobs, DABs, Apps, AI, Private Network Gateway
The video covers multiple new updates in Databricks, including Lakeflow connectors, task value loops, state repartitioning, DAB enhancements, SQL functions, serverless version 6, Unity Catalog skills, app spaces, and network gateways. It demonstrates how to configure Lakeflow job tasks, implement task value loops, and manage serverless compute permissions and environments.
Anyone tried Declarative Pipelines for metadata driven pipelines?
I've been trying out Lakeflow declarative pipelines for a transformation framework I'm building, and it looked like a really good fit. The idea is to drive transformations from contracts rather than maintain a separate table declaration for each table/pipeline for each final object. Depending on the configuration, the framework handles full or incremental loads and SCD1/SCD2. Having the dependency graph and DQ expectations in the same place was a big reason I wanted to try it. I built a POC, and there's a lot I like about the approach. Where I'm getting stuck is fitting the outputs to the client's existing conventions. For example, with AUTO CDC's SCD2 handling, we get __START_AT and __END_AT , while the client expects specific validity/watermark column names and an isCurrent field. We also have other required fields to preserve in the output. These conventions are already used downstream, so changing them means more than updating the pipeline. A view could handle the SCD2 naming and derive isCurrent . That part is doable. But as I work through the remaining requirements, I'm adding more logic around the pipeline outputs, and I'm less sure how much simpler the overall solution would end up being. That's the trade-off I'm trying to work out. Declarative pipelines covered a lot of what I wanted, but accommodating the existing requirements adds overhead that makes it harder to justify adopting them for this particular solution. At the moment, it doesn't look likely, although I haven't ruled it out. What are you using declarative pipelines for? Have you run into similar issues fitting them into an existing setup, and did you find the extra layers worth maintaining? submitted by /u/postnav64 [link] [comments]
Databricks in a SaaS product, and the realtime mode
Hey everyone, i have two questions about databricks and I’d like to hear about your experiences: 1. I have seen a lot of companies who use databricks for their own internal needs and that makes sense. But have you ever seen a SaaS product that uses databricks? For example a products that process customer data to provide some value? Do you know if there is any company that uses databricks structured streaming realtime mode in production? Do you know if they are happy with it? I am asking this because it is a new offering and there is no support for features such as auto scaling (unless if you are using lakeflow pipelines). And i assume it is super expensive as you need a core for every task slot. submitted by /u/shanfamous [link] [comments]
 Tutorials
Demo: Intelligent Document Processing in Databricks | Feat. Databricks' Sepi
The video demonstrates how to use Databricks for intelligent document processing by parsing, classifying, and extracting information from documents using AI functions. It shows an end-to-end workflow where documents are uploaded to a volume, parsed, classified by type, and used for data extraction and automated workflows.
Possible bug in Lakeflow Connect SQL Server ingestion with GUID primary keys – Missing records
trim_array: remove elements from an array
Databricks runtime 19 brings the new Spark function trim_array. trim_array(array(‘A’, ‘B’, ‘C’, ‘D’), 2) returns [‘A’, ‘B’]. A count of 0 keeps the array; a count equal to its length returns an empty array. https://medium.com/databrickscommunity/databricks-news-serverless-genie-code-ltap-lakeflow-61853d8e422a submitted by /u/hubert-dudek [link] [comments]
The New Databricks Lakeflow Designer Is a Game Changer!
Resize streaming partitions
On-demand state repartitioning lets you change streaming state partitions while the stream is still running: set spark.sql.streaming.stateStore.partitions and restart the streaming query, or set it in a Lakeflow table’s spark_conf before the next update. The ability to finally handle complicated scenarios liek that one in Declarative Pipelines is also a big improvement. And checkpoints survive repartitioning. more news https://medium.com/databrickscommunity/databricks-news-serverless-genie-code-ltap-lakeflow-61853d8e422a submitted by /u/hubert-dudek [link] [comments]
Get Tuesday's version of this
Tracking LakeFlow? The Tuesday email carries what moved across the whole ecosystem, not just this topic. Free, one-click unsubscribe.