
Model Serving
Recent items mentioning Model Serving across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Recent reference designs integrate Model Serving with Lakebase and AI Search for low-latency recommendation pipelines 1, while serverless GPU endpoints can now be queried directly within SQL and Lakeflow workflows using ai_query 2. Concurrently, breaking changes across the Python 8 and Go 6 Databricks SDKs remove routing and rate-limiting configuration fields from model serving APIs, alongside an MLflow patch resolving trace location resolution on served endpoints 5.
Generated daily from the 8 most recent items mentioning Model Serving. Click any [N] to jump to the source.
Real-Time Retail Intelligence: Building E-Commerce Recommendations with Lakebase and AI Search on Databricks
A complete reference architecture is now available for building a real-time, multi-stage e-commerce recommendation engine on Databricks using AI Search for candidate retrieval, Lakebase for online feature serving, and Model Serving for low-latency inference. By unifying batch precomputation and real-time scoring on a single governed platform, this design replaces fragmented ML stacks to eliminate glue code and deliver end-to-end lineage from raw clickstream to production predictions.
Running open-Jev in SQL on Databricks
Run models like SemIf-OpenJev directly on governed Databricks data using serverless GPUs and managed Model Serving. Query custom endpoints from SQL or Lakeflow jobs using ai_query to return structured decisions and probability scores at scale, with an importable notebook to deploy and adapt the workflow.
 News
How adidas Uses Databricks to Build Better Products
Adidas uses Databricks' lakehouse platform to centralize all its data—from product to football-related insights—enabling faster analytics across the organization. The company's Genie analytics tool helps analysts spend less time processing data and more time on strategic questions, ultimately supporting better product development.
Multi-region model serving on Databricks with OpenSharing
MLflow 3.16.1
MLflow 3.16.1 removes the default basic-auth admin password from basic_auth.ini as a security fix (GHSA-gq3w-7jj3-x7gr) and adds support for span links in Unity Catalog traces. The release also fixes trace location resolution in Databricks Model Serving, includes a timeout option for the @scorer decorator, and improves web UI access control for non-admin users.
Release introduces three new workspace services (AI Functions, Domains, Sandbox), extends Feature Engineering with new backfill and operation management methods, and adds AWS Secrets Manager and Azure Key Vault connection support. Multiple breaking changes remove fields from model serving and catalog configurations that may require code updates.
MLflow 3.16.0
MLflow 3.16.0 makes the redesigned trace explorer the default interface, introducing natural-language custom trace views via the MLflow Assistant, session grouping for multi-turn conversations, and span links. The update also adds Unity Catalog model service support for built-in evaluation judges, per-user AI Gateway budget policies, and fail-closed authorization by default.
The SDK adds an execute_command_sync() method for sandbox and new fields for ML features (mode, time_window, full_feature_name). Breaking changes remove routing and rate limiting configuration fields from model serving APIs.
Model Serving An internal error occurred during feature store lookup all deploys failing
 News
How AI and Data Keep 2.3 Million Lawns Healthy | TruGreen & Databricks
TruGreen uses Databricks Genie and Lakehouse to manage 2.3 million lawns with AI that optimizes service timing and predicts customer churn using weather, soil, and service data. The system enables non-technical branch managers to take daily actions through customized reports without requiring data expertise.
The CLI adds databricks environments setup-local to provision matched Python environments for Databricks compute targets and extends aitools install to support Gemini CLI and Pi. Bundles fix the ignored bundle.deployment.lock.force setting, add pipeline cascade_on_destroy control, improve experimental job_runs with idempotency tokens and completion waiting, and add UC secrets resource support.
 News
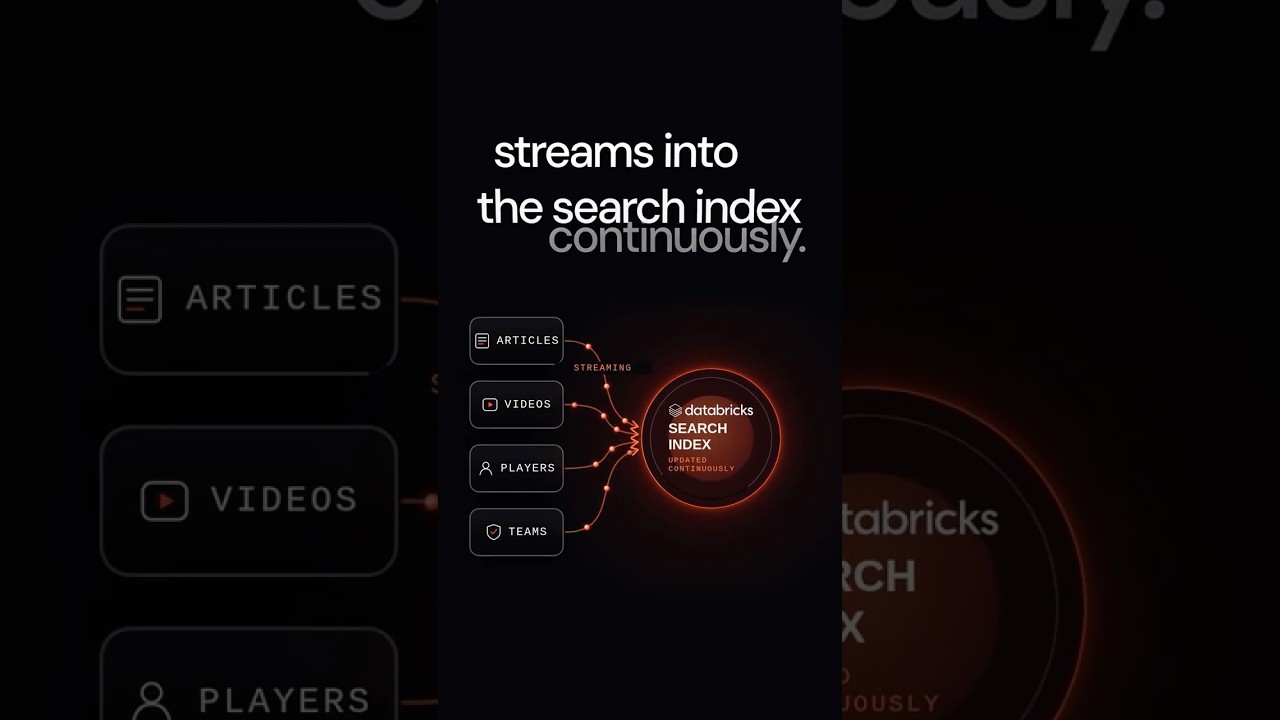
How FOX Sports Uses AI to Power Search
Fox Sports rebuilt their search system on Databricks to handle rapidly changing sports information by continuously streaming player, team, and content data into the index while computing real-time trends. The system uses semantic vector search with time-weighted ranking to surface fresh content higher, doubling the rate at which users find what they're looking for.
 Tutorials
Detect Energy Theft Faster with Genie
Databricks demonstrates an end-to-end AI application that detects energy theft, automates investigations, and generates executive reports using Unity Catalog and Genie. The video walks through an architecture featuring Lakebase for transactional storage, model serving for machine learning and LLMs, and AI gateways for governance and cost control.
This release adds effective entitlements to workspace assignment details and serverless compute ID support for job clusters. It also updates model serving telemetry configurations to include fields for table names and telemetry profile IDs.
What happens in the milliseconds after you tap pay
This sample Databricks App demonstrates how to achieve low-latency real-time fraud scoring by pairing route-optimized Model Serving with Lakebase Postgres for online feature lookups. Under load testing of 5,000 requests, this architecture achieved end-to-end latencies of 27 ms at p50 and 37 ms at p95 while maintaining a 100% success rate.
The SDK now supports specifying a parent path for jobs and associating a Git credential ID with workspace repositories. Model serving configurations now include CpuLarge and CpuMedium options for workload types.
The Java SDK adds a parent path field for job creation and settings, along with git credential ID support for workspace repositories. It also introduces CPU_MEDIUM and CPU_LARGE workload type enums for Model Serving.
Databricks AI Model Serving in production: scaling, cost, and latency lessons
SSH connect adds --base-environment for custom base environments, and aitools install now uses plugins instead of raw skills. Bundle deployments fix drift on model serving endpoints and failed migrations on permissioned resources.
A breaking fix ensures query parameters specified in ForceSendFields are now explicitly sent over the wire even when holding zero values. Additionally, new API updates add support for Genie conversation visualizations, telemetry configuration on model serving endpoints, and expanded Postgres service options.
Databricks and NVIDIA: Building for the Agentic Era
Databricks and NVIDIA are expanding their collaboration to deliver an end-to-end AI platform, accelerating model training, inference, and agentic AI development on governed enterprise data. This includes multinode training in AI Runtime, GPU support in Databricks Free Edition, Model Serving Enhancements, and support for NVIDIA Agent Toolkit and industry-specific AI frameworks.
What’s New in the AI Platform: Agents for ML Engineering, Our Deep Learning Platform, and New Capabilities for Real-Time ML
Databricks shipped Genie Code, a coding agent for ML engineering, and AI Runtime, a serverless GPU platform for deep learning. Power real-time ML at scale with new Feature Store and Model Serving capabilities, including streaming features and high-QPS serving.
How ERGO Hestia reduced time-to-market with Lakebase and Mosaic AI Model Serving
ERGO Hestia modernized its real-time pricing engine with Databricks Lakebase and Mosaic AI Model Serving, reducing time-to-market by unifying data, features, and decisions for millisecond pricing. This eliminated extraction overhead and fragmented governance from their previous multi-hop architecture, enabling faster model deployment and instant market response.
Azure OpenAI v1 API support for External Model Serving / Mosaic AI Gateway?
Databricks Model Serving: The Complete Guide to Production ML at Scale
 News
Banks' Secret Weapon Against Money Laundering: Multi-Agent AI
Databricks demonstrates a multi-agent AI solution for Anti-Money Laundering (AML) operations, significantly reducing false positives and accelerating investigation cycles from hours to minutes. The platform unifies siloed systems, employs specialized AI agents for analysis and recommendations, and offers AI-assisted SAR generation and executive-level reporting with natural language chat.
Unable to make fresh deployments to an agent model serving endpoint due to permission issues
 News
Databricks Apps vs Model Serving: Authentication, Cost, and Performance Compared
Databricks Apps are now the recommended first choice for deploying agents due to their flexibility in handling full-stack applications with multiple components, offering faster iteration and local testing compared to Model Serving. Model Serving remains suitable for use cases prioritizing high QPS, governance features like AI Gateway, inference tables, and guardrails, or when scaling to zero is acceptable for cost optimization.
MLflow 3.11.1 introduces AI-powered issue detection in traces, AI Gateway budget alerts and spending controls, trace graph visualization, native Databricks gateway provider, and pickle-free model serialization. TypeScript SDK packages are now @mlflow-scoped and LiteLLM is no longer required for GenAI evaluation.
Databricks SDK for Python now supports new fields for defining ingestion pipelines, including connector type, data staging options, and detailed ingestion source information. External function requests in model serving can now specify a sub-domain.
ETL Migration to Databricks via LLM Transpilation
I have several ETL jobs from DataStage in .dsx format. I use a PowerShell script to automatically run the migration for a larger number of files. And one job migrates successfully, while another similar one no longer migrates. My code: $jobsPath = "C:\lakebridge_test\jobs" Get-ChildItem $jobsPath -Filter *.dsx | ForEach-Object { $inputFile = $_.FullName $outputPath = "/Workspace/Users/xxx/lakebridge_out/$($_.BaseName)" $psi = New-Object System.Diagnostics.ProcessStartInfo $psi.FileName = "C:\Users\xxx\Desktop\xxx\lakebridge\databricks_cli_0.258.0_windows_amd64\databricks.exe" $psi.Arguments = @( "labs lakebridge llm-transpile", "--input-source `"$inputFile`"", "--output-ws-folder `"$outputPath`"", "--volume lakebridge_vol", "--catalog-name uc-test", "--schema-name lakebridge_test", "--source-dialect unknown_etl", "--accept-terms=true", "--profile lakebridge" ) -join " " $psi.RedirectStandardInput = $true $psi.RedirectStandardOutput = $true $psi.RedirectStandardError = $true $psi.UseShellExecute = $false $psi.CreateNoWindow = $true $process = [System.Diagnostics.Process]::Start($psi) $process.StandardInput.WriteLine("0") $process.StandardInput.Close() $stdout = $process.StandardOutput.ReadToEnd() $stderr = $process.StandardError.ReadToEnd() $process.WaitForExit() Write-Host "==== $($_.Name) ====" Write-Host $stdout if ($process.ExitCode -ne 0) { Write-Error "FAIL: $($_.Name)" Write-Error $stderr } } It automatically selects: Select a Foundation Model serving endpoint: [0] [Recommended] databricks-claude-sonnet-4-5 and starts the migration process to Databricks. A job consisting of a dataset and a Db2 connector migrates correctly, but a job with dataset → Transformer Stage → Db2 connector fails and returns: Exception: No records found for conversion. Please check if there are any records wit […truncated]





Get Tuesday's version of this
Tracking Model Serving? The Tuesday email carries what moved across the whole ecosystem, not just this topic. Free, one-click unsubscribe.