
MLflow
Recent items mentioning MLflow across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
What is MLflow?
MLflow is an open source platform for managing the lifecycle of machine learning models and, increasingly, LLM applications and agents. It tracks experiments (parameters, metrics, artifacts, code versions), packages models and agents in a standardized format, and registers them for versioned deployment. Databricks offers a fully managed and hosted version that builds on the open source experience, with the Model Registry integrated into Unity Catalog.
The problem it solves is losing track of what produced what. Without lifecycle tracking you can't reproduce a model, compare candidate versions, or explain an agent's behavior in production. MLflow Tracing records the inputs, outputs, and metadata of each intermediate step an application takes, which turns debugging and auditing from guesswork into reading a trace.
MLflow 3 moved the project's center of gravity toward generative AI: observability, evaluation with built-in LLM judges, and prompt management for agents and LLM apps, plus new concepts like Logged Models and Deployment Jobs. On Databricks, the managed version adds enterprise features such as encryption with customer-managed keys.
Is MLflow free?
The open source project is free to self-host. On Databricks you get a fully managed and hosted version that builds on the open source experience and adds enterprise security, disaster recovery, encryption with customer-managed keys, and tight Unity Catalog integration.
What's new in MLflow 3 compared to MLflow 2?
MLflow 3 centers on GenAI: end-to-end tracing for agent-based systems, evaluation with built-in LLM judges for safety, relevance, and correctness, and centralized prompt management with versioning and Unity Catalog integration. It also introduces the LoggedModel entity for organizing and comparing model variants, plus Deployment Jobs, with automatic tracing integrations for many popular GenAI libraries and frameworks.
Is MLflow only for classical machine learning?
No. MLflow Models is a standardized format for packaging both machine learning models and AI agents, and MLflow Tracing records the inputs, outputs, and metadata of each step a GenAI application takes. Databricks positions MLflow evaluation and monitoring for agents and ML models alike.
How does MLflow relate to Unity Catalog?
On Databricks, the MLflow Model Registry is integrated with Unity Catalog, so models are versioned and governed alongside your other data and AI assets. That gives you centralized governance and model lineage tracking, plus the ability to access models across workspaces and discover them for reuse.
Sources: MLflow on Databricks (Databricks docs) · MLflow 3 for GenAI (Databricks docs) · MLflow 3 release notes (mlflow.org)
MLflow 2.11.5 introduces an opt-in mechanism to route Unity Catalog model registry artifact uploads and downloads directly through the Databricks SDK Files API 10. Meanwhile, Databricks is standardizing MLflow execution tracing for AI agents managed under Unity AI Gateway 2, ahead of MLflow 3.17's planned integration with TypeSafe's Jev model for high-throughput QA evaluation 7.
Generated daily from the 10 most recent items mentioning MLflow. Click any [N] to jump to the source.
How to fit ~1GB+ embedding model into a 2Gi Kubernetes pod? Getting OOMKilled
Hi, Deploying a FastAPI to Kubernetes that uses a multilingual sentence-transformers embedding model (ONNX backend, CPU only). My source data lives in a Delta table in Databricks, and the app reads from it and generates embeddings. The app takes user input (text) at embeds it, and compares it against stored embeddings for semantic similarity. So at least the query embedding has to happen live. Pod resources: - CPU: 1 request / 2 limit - Memory: 2Gi request = 2Gi limit (platform policy requires memory request and limit to be 1:1) Current docker setup: - Multi-stage Docker build (python:3.11-slim) - CPU-only PyTorch - The model is downloaded at build time, so it's baked into the image Image breakdown: - HF model cache: ~1.1 GB - torch: ~650 MB - pyarrow, scipy, transformers, pandas: ~100–150 MB each - Plus sklearn, onnxruntime, mlflow, and others The pod gets OOMKilled at startup or shortly after. With a ~1GB model, torch, pandas/pyarrow, and the ONNX runtime session all in one process, I think I'm just over 2Gi. What I'm trying to figure out on where do you store large models in production? Would love to hear what setups have worked for you. Thanks! submitted by /u/runningnozone [link] [comments]
 Events
Demo: Building a Governed AI Agent with Unity AI Gateway
This video demonstrates how to build, update, and govern a store operations AI agent using Databricks Agent Bricks and the Unity AI Gateway. The tutorial highlights integrating custom Model Context Protocol servers, recording execution traces with MLflow, and enforcing security policies and budget controls.
MLflow traces accepted by StartTraceV3 (200 OK) but never stored: GetTrace returns NOT_FOUND
The CLI introduces a preview image push command for the Databricks Artifact Registry, preconfigures coding assistants in serverless SSH sessions, and adds expiration flags for Postgres branch creation. In Asset Bundles, clusters now support library configurations, Terraform deployments migrate to the direct engine prior to execution, and Postgres snapshot schedules are restricted to YAML.
Workshop on bringing systematic evaluation and MLflow tracking to LLM apps, Oct 3
If you're already using MLflow for experiment tracking on the ML side, there's a decent chance your LLM work hasn't caught up to the same standard yet. Most teams are still hand-tuning prompts and eyeballing outputs while everything else in the stack gets versioned and tracked properly. Serj Smorodinsky and Brett Kennedy, co-authors of a book on LLM applications, are running a live 3-hour workshop on Oct 3 that applies that same rigor to LLM development. What's covered: Programming LLM behavior with DSPy signatures and modules instead of hand-written prompt strings Building a baseline classifier live, from a real task Constructing an evaluation dataset with task-specific metrics so "better" is measurable, not a feeling Reading failure patterns directly out of the eval results Few-shot and instruction-level optimization applied systematically on top of the baseline Experiment tracking and LLM trace management through MLflow, so every run is reproducible and comparable Saving and reusing optimized DSPy programs across projects Communicating LLM reliability to stakeholders, which usually gets skipped entirely It's basically the MLflow discipline this community already applies to models, extended to prompts and LLM pipelines. Aimed at people already past "which model should I use" and into "how do I make this reliable." Full details here. submitted by /u/camerongreen95 [link] [comments]
Can Jev replace your LLM judge? Part 2: Testing harder answers
TypeSafe's Jev model evaluates MLflow QA answers roughly seven times faster and significantly cheaper than larger LLMs, but it misses subtly incorrect technical details such as reversed roles and omitted permissions. Ahead of Jev integration arriving in MLflow 3.17, practitioners can use its confidence probabilities to fast-track clear verdicts while escalating borderline cases to a larger model for review.
Laya off the benchmark: can a zero-shot decision model route real SQL traffic?
Weekend-ish experiment on Databricks. One table, TPC-H orders, 15M rows, living in two places at once: Lakebase (Databricks' managed Postgres), a continuously synced copy with a btree index on the key. Sub-100ms point lookups, useless for a GROUP BY over 15M rows. Delta behind a serverless SQL Warehouse. Great at scans and aggregations, slow at fetching one row. The synced table is the nice part: native continuous Delta to Lakebase Postgres (needs a PK + CDF), so it's one dataset under one Unity Catalog, replication handled by the platform instead of a homemade pipeline. Then I put laya (convaiinnovations/laya, a non-autoregressive zero-shot decision model, vanilla, no fine-tuning) behind a FastAPI Databricks App. It reads each query and picks the engine. MLflow traces input to decision to execution. I submitted by /u/Limp-Park7849 [link] [comments]
AI Runtime commands have moved from experimental to databricks air, and SSH commands now support keeping detached background processes running after tunnel disconnect. Databricks Asset Bundles direct engine resolved multiple issues around unnecessary resource recreations, Unity Catalog grant convergence, and Git-sourced Python tasks.
MLflow 2.11.5
Users can now opt in to route Unity Catalog model registry artifact uploads and downloads through the Databricks SDK Files API. This update provides an alternative transfer mechanism for managing model artifacts within Databricks environments.
Can Jev replace your LLM judge? Evaluating quality, cost, and latency
Benchmarking Jev against GPT, Claude, and DeepSeek using MLflow reveals how it measures up as an alternative LLM judge. Review side-by-side performance across quality, cost, and latency to see if Jev can replace your current evaluation models.
 News
How adidas Uses Databricks to Build Better Products
Adidas uses Databricks' lakehouse platform to centralize all its data—from product to football-related insights—enabling faster analytics across the organization. The company's Genie analytics tool helps analysts spend less time processing data and more time on strategic questions, ultimately supporting better product development.
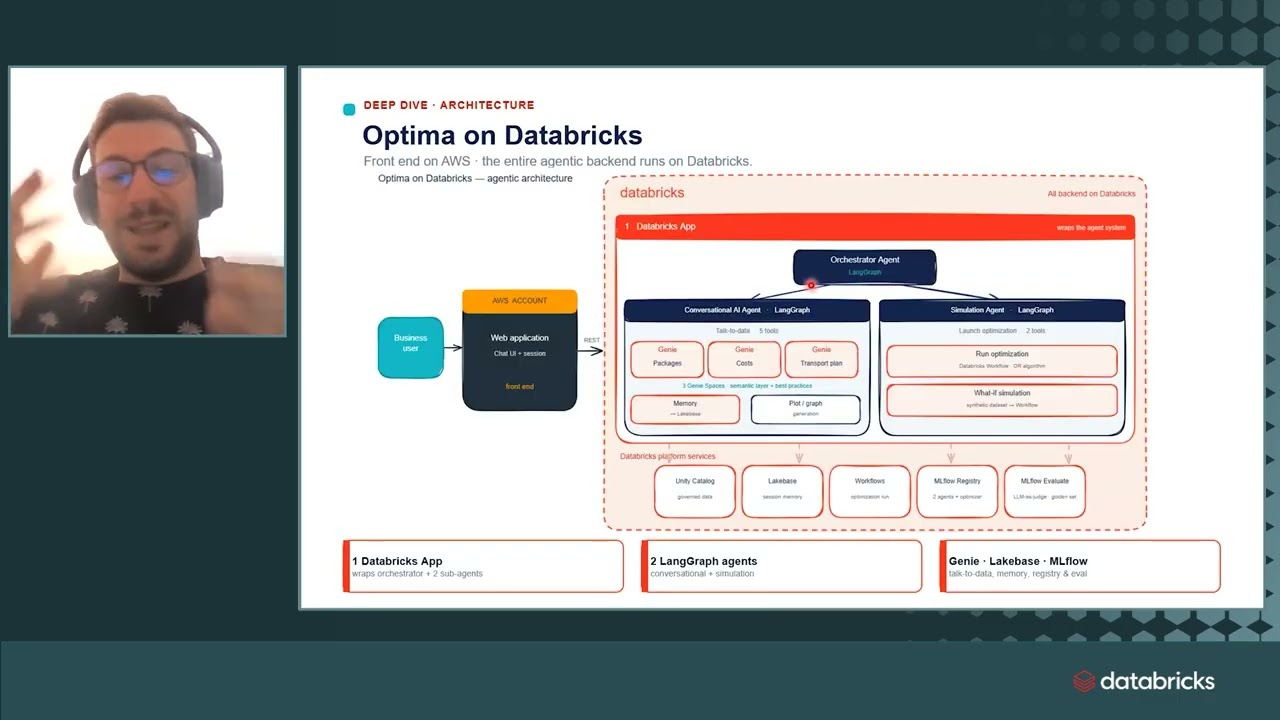
Building Custom Agents on Databricks:LangGraph, Atlan-Grounded Routing, and Per-Run Cost with MLflow
MLflow 3.16.1
MLflow 3.16.1 removes the default basic-auth admin password from basic_auth.ini as a security fix (GHSA-gq3w-7jj3-x7gr) and adds support for span links in Unity Catalog traces. The release also fixes trace location resolution in Databricks Model Serving, includes a timeout option for the @scorer decorator, and improves web UI access control for non-admin users.
Could a “Data → Agent” composer be useful for Databricks?
I've been thinking about a gap between Databricks data and agent frameworks. Databricks already has a lot of the building blocks: - Unity Catalog - Genie / Genie Agents - MCP - Vector Search - AI Gateway - Agent skills/tools - MLflow - Omnigent / Kasal And tools like Omnigent and Kasal already solve a lot of the agent orchestration/execution side. But I'm wondering about the step before that: What if a customer already has a large, curated and governed Databricks data estate — how do we turn that data estate into an agent-ready configuration without manually wiring everything together? Something like: Existing Databricks Data Estate ↓ Data-to-Agent Composer ↓ ┌────────┼─────────┐ ↓ ↓ ↓ Domains Semantics Metrics ↓ ↓ ↓ Genie MCP Skills └────────┼─────────┘ ↓ Agent Configuration ↓ Omnigent / Kasal ↓ Agent The idea wouldn't be to build another chatbot or another agent framework. It would be a Databricks-native composition/bootstrapping layer that understands an existing Unity Catalog/data estate and generates the pieces needed for agents to work with that data — domain boundaries, semantic context, approved tools, Genie configuration, MCP exposure, skills, policies, evaluation setup, etc. In other words: Kasal/Omnigent: Agent → Tools/Data Proposed layer: Data Estate → Agent I'm curious if this is already solved somewhere in the Databricks ecosystem, or if people are currently doing this manually when building enterprise data agents. Would love to hear how others are approaching the “existing data estate → production-ready data agent” problem. submitted by /u/imsuryya [link] [comments]
Evaluation-First AI Agents: How Zepto Scales Customer Support on Databricks and MLflow
Zepto built its customer support agents on Databricks and MLflow using an evaluation-first approach, treating traces, golden datasets, and LLM-as-judge checks as core infrastructure and connecting development and production through a dual-loop architecture with a strict quality gate. The result: 65% lower support costs and payback in under a month, giving other AI builders a reusable blueprint for engineering reliability, cost, and risk into production-grade agents.
 Tutorials
How to Build and Serve Production ML Features | Databricks Feature Store Demo
Databricks Feature Store provides a unified feature views abstraction for batch and streaming data with automatic point-in-time joins for training and built-in MLflow experiment tracking. The same feature definitions deploy directly to production with online serving on Lake Base, eliminating the need to rewrite features while enabling model and feature serving to scale together.
Building Custom Agents on Databricks:LangGraph, Atlan-Grounded Routing, and Per-Run Cost with MLflow
MLflow 3.16.0
MLflow 3.16.0 makes the redesigned trace explorer the default interface, introducing natural-language custom trace views via the MLflow Assistant, session grouping for multi-turn conversations, and span links. The update also adds Unity Catalog model service support for built-in evaluation judges, per-user AI Gateway budget policies, and fail-closed authorization by default.
Difference between Workspace and Unity Catalog experiments when using MLflow autologging?
How are you actually setting up AI/LLM evals in Databricks end-to-end? Looking for a step-by-step production workflow
We have a product where Databricks is our backend , and we’re now trying to properly evaluate and improve the quality of the AI-generated answers in our application. I’m looking for advice from people who have actually implemented LLM/GenAI evaluations in Databricks in production . I’d really appreciate an end-to-end, step-by-step explanation of how you would set this up from scratch. Specifically, how would you approach: Define what a “good answer” means Accuracy / correctness Relevance Completeness Groundedness / faithfulness to our data Hallucination rate Citation/source correctness Following user instructions Response consistency Latency and cost Create a benchmark / golden dataset Should we manually create a set of representative user questions? How many questions are enough to start? Should each question have an expected answer? Should we store expected SQL/results, expected sources, or just an expected natural-language response? Where should this benchmark dataset live in Databricks? How do you keep it updated as the product evolves? Set up automated evaluations What Databricks/MLflow tools should we be using today? MLflow evaluation? LLM-as-a-judge? Custom scorers? Human evaluation? How do you combine these rather than relying on one score? Evaluate RAG / data-grounded answers Our AI answers questions based on enterprise data in Databricks. How do you separately evaluate: Retrieval quality Whether the correct tables/documents were selected Context relevance Groundedness Final answer correctness Whether the model invented something that wasn’t in the retrieved data Evaluate text-to-SQL / analytics questions If a user asks something like: “What was average building occupancy last month?” should we evaluate: Generated SQL Tables selected SQL execution result Final natural-language answer separately? What is the recommended architecture for this? Guardrails Where should guardrails sit in the architecture? For example: Prevent hallucinated numbers Prevent querying unauthorized tables Detect PII Prevent prompt injection Enforce tenant/user permissions Block unsupported questions Force answers to cite their source Return “I don’t know” when confidence is too low Should guardrails be part of evaluation, inference, or both? Production monitoring Once this is live, what should we log for every AI request? For example: User question → retrieved context → generated SQL/tool calls → query result → final response → model → prompt version → latency → tokens → cost → evaluation scores → user feedback Is that roughly the right model? Regression testing When we change: System prompt Model Retrieval strategy SQL generation logic Tools Temperature Data sources how do you automatically run the benchmark again and determine whether the new version is actually better? Do you set minimum score thresholds before allowing something to deploy? Human feedback How are people incorporating thumbs-up/down or analyst review into their evaluation datasets? Do production failures automatically become new benchmark cases? Making answers more precise This is ultimately my main goal. If our AI currently gives an answer that is “mostly correct,” what is the systematic process for figuring out why it isn’t fully correct? Is the best workflow something like: Production traces → identify failure → categorize failure → add to benchmark → improve retrieval/prompt/tool → run eval → compare against baseline → deploy → monitor Or is there a better approach? I’m especially interested in what the ideal Databricks-native architecture looks like: User Question → Agent / LLM → Retrieval / SQL / Tools → Databricks data → Response → MLflow tracing → Automated evaluators → Benchmark dataset → Regression testing → Production monitoring If you’ve implemented something like this, I’d love to know what you would build first, second, third, etc. Even a practical example like: Week 1: create benchmark Week 2: add tracing + scorers Week 3: add regression tests Week 4: add guardr […truncated]
MLflow 3.15.2 introduces immutable evaluation dataset versions and a scorer_ensemble primitive for combining scorer results. The patch also fixes a Databricks telemetry deadlock and addresses issues in MemAlign aligned judges and runs.status constraint handling.
 Events
Building Governed Agents with Databricks
Databricks extends its Unity Catalog governance layer to AI agents, MCP servers, and tools to solve "agent sprawl" by providing centralized discovery, access controls, and audit logging. The system allows developers to quickly build agents while IT teams enforce fine-grained policies, manage credentials, and track end-to-end request and response lineage.
 News
AI Runtime CLI | Serverless GPU LLM Training
Databricks AI Runtime is a CLI tool that enables distributed LLM training on serverless GPUs using YAML configuration files, supporting deployments up to 256 H100 GPUs with built-in MLflow experiment tracking and hardware metrics. Users develop training code locally in their preferred environment and submit jobs via CLI commands that automatically handle infrastructure provisioning, log streaming, and performance monitoring.
 News
How AI and Data Keep 2.3 Million Lawns Healthy | TruGreen & Databricks
TruGreen uses Databricks Genie and Lakehouse to manage 2.3 million lawns with AI that optimizes service timing and predicts customer churn using weather, soil, and service data. The system enables non-technical branch managers to take daily actions through customized reports without requiring data expertise.
 News
Databricks News: ZeroOps, DABs, Indexes, Genie, sandboxes, migration from PowerBI, secrets
Zero Ops automatically detects errors in jobs and data quality with lineage analysis and proposes code fixes, while DABs now default to direct mode instead of Terraform with automatic state migration. Full-text search indexes deliver 400x faster queries on billion-row tables, Genie automatically converts PowerBI dashboards to Databricks metric views, and Unity Catalog secrets support granular read and reference-only permissions.
Job definitions now support trigger configuration and MLflow artifact location for AI runtime tasks. Pipeline connector options and GCP endpoint settings have been expanded with new configuration fields.
The SDK now supports job triggers and MLflow artifact locations in the Jobs API, enabling more flexible job scheduling and artifact management. New connector configuration options are available for Pipelines, and GCP endpoint settings have been expanded.
 News
Building Agents on Databricks with Custom Apps and Omnigent
This video demonstrates how to build, update, and govern custom AI agents on Databricks using Agent Bricks, Databricks Apps, and Omnigent. The tutorial shows how to integrate Model Context Protocol servers, track execution with MLflow traces, schedule automated agent tasks, and manage security policies through Unity AI Gateway.
 Tutorials
Building Agents on Databricks with Custom Apps and Omnigent
The video demonstrates how to build, update, and govern a store operations AI agent on Databricks using Model Context Protocol servers and custom apps. It shows how to use Omnigent and CodeX to add new context and tools, redeploy the application, and manage governance and traces through the Unity AI gateway.
 News
AI for Mental Health: Crisis Text Line and Databricks
Crisis Text Line provides 24/7 text-based mental health support to millions of individuals facing crises like anxiety, bullying, and financial hardship. The organization uses the Databricks platform to safely analyze anonymized conversation data and improve how researchers understand and serve people in need.
MLflow 3.15.1
MLflow 3.15.1 fixes version parsing issues on Databricks Serverless and corrects env_pack behavior on ARM client images. Scorer versioning documentation has been clarified.
Evaluating and Improving Agent Skills with MLflow
MLflow enables evaluation-driven development for AI agent skills by combining traces, evaluation datasets, custom evaluators, and experiment tracking to treat agent capabilities like testable software components. Instead of grading only final outputs, teams can use execution traces to systematically measure critical behaviors such as tool sequencing, policy compliance, and execution efficiency across skill iterations.
MLflow 3.15.0 introduces an MCP Registry for registering and sharing Model Context Protocol servers, enhances the Assistant with multi-provider LLM support and per-session token usage tracking, and enables proxy-less artifact transfers via presigned URLs to reduce server load and timeouts on large files. Additional improvements include sharable Runs table views, multi-modal image attachments for LLM judges to evaluate vision tasks, and numerous bug fixes across tracing, evaluation, gateway, and UI components.
Workspace ID validation for unified-provider resources shifted from plan time to apply time, reducing unnecessary API calls and eliminating false positives for restricted credentials and dynamic workspace IDs. The release adds a databricks_recipients data source for Delta Sharing, trace_location support for MLflow experiment traces in Unity Catalog, and fixes for VIEW column comment updates and access control rule set drift detection.
Simplify AI agent orchestration with Lakebase Postgres
Lakebase Postgres can serve as a durable, crash-resilient task queue for long-running AI agent workflows without requiring an external broker, cache, or scheduler. This native reference architecture connects Databricks Apps, Lakeflow Jobs, MLflow, and Unity Catalog Volumes into an end-to-end agentic pipeline featuring real-time task and cost tracking via Postgres LISTEN/NOTIFY triggers.
How Dow Built a Carbon Footprint Ledger on Databricks to Accelerate Sustainability at Scale
Dow built an enterprise Carbon Footprint Ledger on the Databricks Data Intelligence Platform, collapsing cradle-to-gate Product Carbon Footprint calculation times from weeks to a fraction of that across its entire portfolio. Powered by Apache Spark, Delta Lake, Unity Catalog, and MLflow, the solution delivers full data lineage and audit-grade governance designed for third-party assurance against ISO 14067 and GHG Protocol standards.
Building a soccer coaching app on Databricks
Coach's Corner is a Databricks App that processes 25 fps match tracking data into a sub-second 2D/3D tactical bench with replays, event analytics, a scout chat, and an opponent-dossier agent. The end-to-end solution is powered entirely on the Databricks platform, utilizing Lakeflow pipelines for data refinement, DBSQL and Lakebase for rapid querying, and Unity Catalog-governed AI tools like Genie, Vector Search, and MLflow tracing.
E2E MLOps Part 1: How to build and govern models with AutoML, MLflow, and Unity Catalog
Data-Native AI Agents: Why Agents Must Move to Your Data
AI agents must run directly within your data stack rather than in a separate, external stack to avoid compounding penalties like fragmented governance, high egress costs, and latency. By deploying data-native agents on the Databricks Data Intelligence Platform, enterprises can leverage an integrated stack of Unity Catalog, AI Search, MLflow, Lakebase, and AI Gateway to ship secure, trusted AI features faster.
 News
Databricks News: RT Lakehouse (Reyden), Lakebase, TTL
This video highlights recent Databricks updates, including the beta release of the high-performance "Raiden" real-time lakehouse engine and new lakeflow connectors. It also demonstrates administrative changes to user groups, new time data types, predictive optimization TTL deletes, user home volumes, and advanced search capabilities in Lakebase.
The Databricks Go SDK updated job run structures to include deployment and version ID fields. MLflow experiment objects now support trace locations, and disaster recovery stable URLs include a stable workspace ID field.
Review Queues: The Human Step Towards Better AI
MLflow Review Queues turn AI trace review into a ticketing system equipped with assignments, status tracking, and human evaluations. Teams can now move away from tracking AI degradations and misbehavior in spreadsheets.
Multi-Harness AI Agents Need Multi-Layer Observability: Omnigent in MLflow
Omnigent unifies multi-harness agent orchestration and now delivers automatic observability across every agent with MLflow Tracing, requiring no code changes. This post details how Omnigent in MLflow provides multi-layer observability for multi-harness AI agents.
MLflow 3.14.0 adds one-command agent setup with Databricks support and durable low-latency Claude Code tracing, Review Queues for trace annotation and feedback collection, and @mlflow.test pytest markers for regression testing. Default model serialization formats change for sklearn to skops, PyTorch to pt2, and LightGBM to skops.
 News
Genie Spaces or Genie Code? Databricks AI Explained
Databricks offers two AI assistants: Genie Spaces for business users to get data answers via natural language queries and multi-task investigations, and Genie Code for technical professionals to build dashboards, write code, generate pipelines, and debug GenAI apps. Spaces is for asking questions, while Code is for building and developing within the Databricks platform.
How to Manage your LLM Teams using MLflow's Role-Based Access Control
MLflow's new Role-Based Access Control (RBAC) helps LLM teams define reusable roles, isolate workspaces, and enforce fine-grained permissions across prompts, experiments, and AI Gateway resources. Learn how to manage your LLM teams using these new MLflow RBAC capabilities.
 Events
Databricks News: CLI v 1.0.0, AI-tools, databricks Docker, DABs UI sync, mutators
The video demonstrates new Databricks features, including the GA release of CLI 1.0.0, UI sync for DABs, Python mutators for bundle extension, and new Docker image options for custom runtimes. It also covers serverless pipeline orchestration, enhanced autoscaling for Lakebase and apps, serverless interactive execution timeout, and auto-scoping for access tokens.
How Ecolab rebuilt retail intelligence on Databricks and Anthropic Claude
Ecolab rebuilt retail intelligence on Databricks and Anthropic Claude, converting 700-page FDA manuals into real-time answers for frontline staff using Foundation Model APIs and cutting compliance report compilation from two weeks to under two minutes. The solution, a native Databricks App with Lakebase Postgres and Unity Catalog, unifies nine siloed data sources and employs a multi-agent orchestration framework with Judge LLMs and MLflow tracing for personalized, continuously refined intelligence.
 Tutorials
Trace Any AI Agent with OTel, MLflow, and Unity Catalog
Databricks now allows sending OpenTelemetry traces from any AI agent to Unity Catalog, enabling end-to-end observability and governance within the Databricks Lakehouse. This integration facilitates cost-effective trace storage, offline analytics, production monitoring, and continuous agent evaluation using MLflow.
 News
Banks' Secret Weapon Against Money Laundering: Multi-Agent AI
Databricks demonstrates a multi-agent AI solution for Anti-Money Laundering (AML) operations, significantly reducing false positives and accelerating investigation cycles from hours to minutes. The platform unifies siloed systems, employs specialized AI agents for analysis and recommendations, and offers AI-assisted SAR generation and executive-level reporting with natural language chat.
MLflow 3.13.0 introduces Role-Based Access Control with Admin UI, automatic trace archival to S3, and one-click observability for Claude Code and other coding agents. Breaking changes include a redesigned permission system (legacy APIs removed), MLServer removal from pyfunc serving, and requirement for MLFLOW_ALLOW_FILE_STORE=true flag for local file-based stores.
Multi-Agent Supervisor for Hybrid Retrieval with Agent Bricks and MLflow
Context Engineer Associate Beta Ex︁am + free attempt at DAIS
Context engineering is quickly becoming one of the key skills for building reliable AI agent systems. Databricks has just introduced the **Databricks Context Engineer Associate** **Ex︁am**, focused on designing, assembling, and governing the information AI agents receive at inference time - including prompts, retrieval systems, memory, tools, governance, and evaluation. The ex︁am is currently available as a **live beta at Data + AI Summit 2026**, and Databricks states that **one free onsite exam attempt will be offered during Summit**. Walk-ins only, one per attendee. Great opportunity for anyone working with GenAI, AI agents, Vector Search, Unity Catalog, MLflow, MCP, or Lakebase. [https://www.databricks.com/learn/certification/context-engineer-associate](https://www.databricks.com/learn/certification/context-engineer-associate)
Route Claude Code Through MLflow AI Gateway
MLflow AI Gateway now supports routing Claude Code, providing full observability, budget controls, and guardrails for all your coding agent sessions. This integration requires no changes to your existing Claude Code usage.
 Tutorials
Building Trustworthy, High-Quality AI Agents with MLflow
Databricks' MLflow platform helps developers build trustworthy, high-quality AI agents by providing tools for end-to-end observability, evaluation, prompt management, and AI gateway governance. It demonstrates how MLflow facilitates tracing, expert feedback collection, automated issue detection with LLM judges, prompt optimization, and continuous monitoring throughout the agent development lifecycle.
 Tutorials
Building Enterprise-Ready Agents using Agent Bricks
Databricks Agent Bricks is a unified platform designed to help enterprises build and manage AI agents, addressing challenges like low-quality reasoning on proprietary data, lack of governance, and fragmented toolchains. It demonstrates how to create knowledge assistants for unstructured data and AI Genies for structured data, integrating with Unity Catalog for governance and MLflow for observability and evaluation.
MLflow 3.13.0rc0 completely overhauls Role-Based Access Control with unified permission APIs and a new Admin UI, and integrates Claude Code, OpenAI, Ollama, and OpenClaw as native assistant providers in the AI Gateway. The release adds trace archival with seamless retrieval, GenAI agent stress-testing, Kubernetes Helm chart support, and database replica routing for horizontal scaling.
Agent Deployment Pattern on Databricks App
Hi all, I'm figuring out what the standard pattern is to deploy an agent to Databricks App. Here's what I found and it is not that clear-cut: \- Pattern 1 (the conventional MLOps way): prepare agent script -> log agent (model-from-code) -> register agent -> deploy to Serving Endpoint \- Pattern 2 (the app template way): prepare agent script -> prepare agent server script (mlflow AgentServer) -> customize or use frontend codes -> deploy to Databricks App From Databricks documentation, pattern 2 is the recommended way to go for a multi-turn, long-running agent, and I can understand why. They even include a guide to migrate the agent from pattern 1 to pattern 2. However, it appears that we "break" the model life cycle process. While pattern 1 can retain all lineage from your experiment, run, catalog all the way to the endpoint, pattern 2 does not. The app becomes an isolated program. If I want to maintain the MLOps practice, I am stopped at the agent registration step, after which I have no pathway from the registered agent to the app. Am I understanding this correctly or there is something missing for pattern 2? Is there a native way to deploy a registered agent from unity catalog to an app? P.S. The training materials for the GenAI Engineering Associate cert is showing pattern 1.
From "What Happened?" to "What Will Happen?"
Conversational BI now delivers predictive answers in seconds, not days, by fusing Genie for dynamic feature engineering with TabPFN for zero-training prediction, orchestrated by Agent Bricks. This self-assembling pipeline eliminates data science bottlenecks for business users, providing a governed experience backed by Unity Catalog and MLflow.
Get Tuesday's version of this
Tracking MLflow? The Tuesday email carries what moved across the whole ecosystem, not just this topic. Free, one-click unsubscribe.