


Cost Optimization
Recent items mentioning Cost Optimization across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Spark declarative pipelines (SDP) improve pipeline cost efficiency by replacing manual ETL scripting with automated orchestration, incremental updates, and engine-level execution 3. Meanwhile, data practitioners looking to control spend are actively seeking tooling beyond native Databricks system tables 1, pointing toward dedicated multi-provider cloud FinOps solutions 2.
Generated daily from the 3 most recent items mentioning Cost Optimization. Click any [N] to jump to the source.
What do you use for Databricks cost optimization beyond system tables?
We’re spending roughly $900 a day in DBUs and a bit over $2k a day on the AWS side for the same workspaces. For a long time, I only had a dashboard for the first number, it’s the usual one on system.billing.usage joined to list_prices and it looked fine until finance put it next to the AWS invoice. Tags get me part of the way because cluster tags land on the EC2 instances and cost explorer can group by them. Most of our scheduled jobs moved onto instance pools last year to cut startup time though, and on pool clusters our custom tags only show up on the DBU side. Idle pool instances don’t appear in system tables at all because they don’t burn DBUs while they sit there but AWS still bills every hour of them. On top of that, about 40 scheduled jobs run on one shared all-purpose cluster and that’s a single line on the EC2 side that I have no fair way to split back to teams. Which tool ended up tying the Databricks and AWS sides together for you, ofcourse past the built-in system tables? submitted by /u/Impressive-Craft1926 [link] [comments]
Cloud FinOps Directory with 40 Providers
Hi everyone! I've recently created a Cloud FinOps Directory featuring 40+ providers, covering FinOps platforms, cloud cost optimization tools, Kubernetes cost management, and more. I’m trying to make the directory the most helpful and useful for the others. I’m looking to expand the providers list, so I'd really appreciate your help. Are there any providers or tools you think should be included? If you are a provider and you’d be interested to be in the list DM me. (It’s free) You can check it out here: https://finops.monetizacreator.com/ submitted by /u/anazt_yt1 [link] [comments]
 News
Why the Creator of Delta Lake Says: Stop Writing ETL
Spark declarative pipelines, or SDP, allow engineers to define what data tables and transformations should exist rather than manually scripting how to execute them, letting the system handle the underlying orchestration, incremental updates, and error handling. Michael Armbrust and Alexandra Chashchina explain how SDP simplifies data pipelines across various workloads, improves cost efficiency, and reduces manual intervention compared to traditional Spark and Delta Live Tables approaches.
Databricks cost optimization: monitoring all-purpose clusters with the API
A practical guide to cost optimization with Lakebase Postgres
Lakebase Postgres delivers low, predictable costs when you sync only the working subset of Lakehouse data, match sync modes to actual freshness needs, and right-size compute so hot data fits in cache. Combining these optimization practices with serverless scale-to-zero, tuned PITR, and shared storage ensures strong performance and availability without paying for unused resources.
Databricks Cost Optimisation 3rd Party Tools
Does anyone have experience with third party optimisation tools like espresso.ai or Zipher? Espresso has an enticing pricing model but I wonder if dumping a whole heap of logs and system stats into Claude would get me 80% of the way there. submitted by /u/Agitated-Western1788 [link] [comments]
NBCUniversal’s Seamless Migration: Unlocking Scalable Analytics with Databricks
NBCUniversal cut costs by 30% by moving from a slot-based reservation model to Databricks' dedicated job compute, letting parallel pipelines scale independently and consistently hit SLA targets. Partner EXL executed the migration in phases with custom accelerators for code conversion, data migration, and automated validation, giving NBCUniversal a unified platform for ML development, real-time analytics, and collaborative data engineering.
The Open-Weight Revolution: A Game Changer for Our LLM Cost Optimization Odyssey
Snowflake to Databricks Migration in 12 weeks and cut cost per run by ~77%. AMA.
Lovelytics wrapped up a Snowflake-to-Databricks migration; 847 DBT models, 35 Info Mart tables, \~77% lower cost per run on a 2XL warehouse. **TL;DR What helped:** * Treated the migration as engineering, not translation. Each dbt model was tested in isolation, not just row counts vs Snowflake. * Routing macro to resolve cross-layer references at runtime, so the same codebase could read from Snowflake, federated Snowflake, and Unity Catalog without forking logic. * Dual model trees in one repo, which let the migration stay in lockstep with live Snowflake changes. * Script-generated wave selectors enabled parallel builds while preserving dependency order. * Used reference-slice validation subsets vs. waiting on full mart refreshes. **TL;DR Cost reduction:** * Reworked joins to use narrow staging dimensions instead of wide marts where possible. * Added incremental predicates to reduce MERGE target scans. * Split wide models into parallel sub-models where the dependency graph allowed it. * Copied static reference data into Delta instead of repeatedly reading it through federation. * Loaded static copies into Delta rather than reading via federation (predicate pushdown is poor). Happy to go into the gotchas: HASH() not being portable, Snowflake MERGE tolerating duplicate keys that Delta doesn't, NULL ordering, and timestamp handling. AMA [Full Blog Post](https://community.databricks.com/t5/technical-blog/partner-blog-847-models-12-weeks-77-less-inside-r1-s-snowflake/ba-p/157284)
Scaling for MHHS: how Octopus Energy achieved a 50x cost reduction in margin data engineering
Octopus Energy achieved a 50x cost reduction in their margin data engineering pipelines by re-architecting on Databricks for UK MHHS regulation. They leveraged Delta Lake Change Data Feed and Databricks Serverless to process 48x more data at a fraction of the original cost, improving freshness from weekly to daily.
How nOps Rebuilt Their Cloud Optimization Platform on Databricks Lakebase, and Why Other ISVs Should Too
nOps migrated its production cloud cost optimization platform to Databricks Lakebase, replacing a separate relational database and custom ETL pipelines with managed PostgreSQL directly integrated into the Lakehouse. The move provides an architectural blueprint for ISVs looking to eliminate synchronization overhead and unify operational and analytical data under a single governance model.
 News
Databricks Apps vs Model Serving: Authentication, Cost, and Performance Compared
Databricks Apps are now the recommended first choice for deploying agents due to their flexibility in handling full-stack applications with multiple components, offering faster iteration and local testing compared to Model Serving. Model Serving remains suitable for use cases prioritizing high QPS, governance features like AI Gateway, inference tables, and guardrails, or when scaling to zero is acceptable for cost optimization.
 News
GPU Accelerated Spark Connect
This video demonstrates how to accelerate Spark Connect using GPUs for both Spark SQL and ML workloads. It details the architecture, deployment, and benchmark results showing significant speedups and cost savings compared to CPU-only execution.
 News
Saving Millions From Millions: Navigating Towards Cost-Efficiency in Pinterest's Spark Jobs
Pinterest built a three-layer cost optimization system for Spark jobs using observability platforms (collecting real-time metrics and event logs), platform innovations (Apache Celeborn remote shuffle service and Kubernetes burst-aware memory allocation), and fine-grained management tools. Production deployments achieved 30-50% cost reductions per job through resource tuning while improving cluster utilization.
 News
Innovating Retail Data: Unilever’s Transformation with Databricks DLT
Unilever replaced its legacy data pipelines with Databricks Delta Live Tables using a medallion architecture, enabling serverless streaming, automated data quality checks, and unified governance through Unity Catalog. The migration delivered 25% infrastructure cost reduction, 200-500% faster data processing, and real-time analytics at scale.
 News
From Code to Insights: Leveraging Advanced Infrastructure and AI Capabilities
Insulet migrated its data infrastructure from Azure to Databricks, implementing a data mesh architecture with medallion layers, Unity Catalog governance, and Delta Sharing for partner data access. The company achieved real-time analytics, GXP-compliant deployments, and FinOps cost optimization, demonstrating how to balance innovation with operational efficiency.
 News
Sponsored: Kyvos | Analytics 100x Faster Lowest Cost w/ Kyvos & Databricks, Even on Trillions Rows
Kyvos is a universal semantic layer and analytics acceleration platform that delivers sub-second query performance on massive datasets with high concurrency. The platform utilizes smart aggregation technology to pre-aggregate data efficiently on disk, allowing companies to replace complex legacy cubes and aggregate tables with a single, highly scalable object.
 Tutorials
Databricks Cost Management: Tips and Tools to Stay Under Budget
Databricks cost management involves tracking usage with billing system tables and cloud tools while optimizing expenses through proper compute sizing and automated job clusters. The platform also provides methods like cluster policies, custom tagging, and alerts to control budgets and attribute costs across different business units.
 Tutorials
DBA Perspective—Optimizing Performance Table-by-Table
The video explains how to scale database administration and optimize lakehouse performance by analyzing metadata to identify tables with too many small files or too few files. It then demonstrates how to resolve these issues by using Databricks runtime updates, table optimizations, Z-ordering, and proper retention and cleanup policies.
 Events
Media and Entertainment Experience at Data + AI Summit 2022
The Communications, Media and Entertainment program at Data + AI Summit 2022 is curated in one place for data teams and executives. It includes an industry forum with HBO, LaLiga, Condé Nast and others, a partner lounge, and over 10 technical talks from companies such as AT&T, Netflix and HuuugeGames.
 News
Accelerate Spark-Based Analytics by Minimizing the Barriers of Large, Complex Hadoop Migration
WANdisco and Avanade present a methodology for migrating petabytes of data from on-premises Hadoop to Azure, removing a common blocker to Spark-based analytics. The approach minimizes migration risk and targets petabyte-scale migration with zero downtime, zero data loss and faster time-to-value.
 News
NLP-Focused Applied ML at Scale for Global Fleet Analytics at ExxonMobil
ExxonMobil uses Databricks to ingest structured and unstructured equipment maintenance logs for its global fleet from legacy systems and apply NLP to millions of records. The resulting insights support outlier identification, capacity planning, prioritization of cost reduction opportunities and discovery for cross-functional teams.
 News
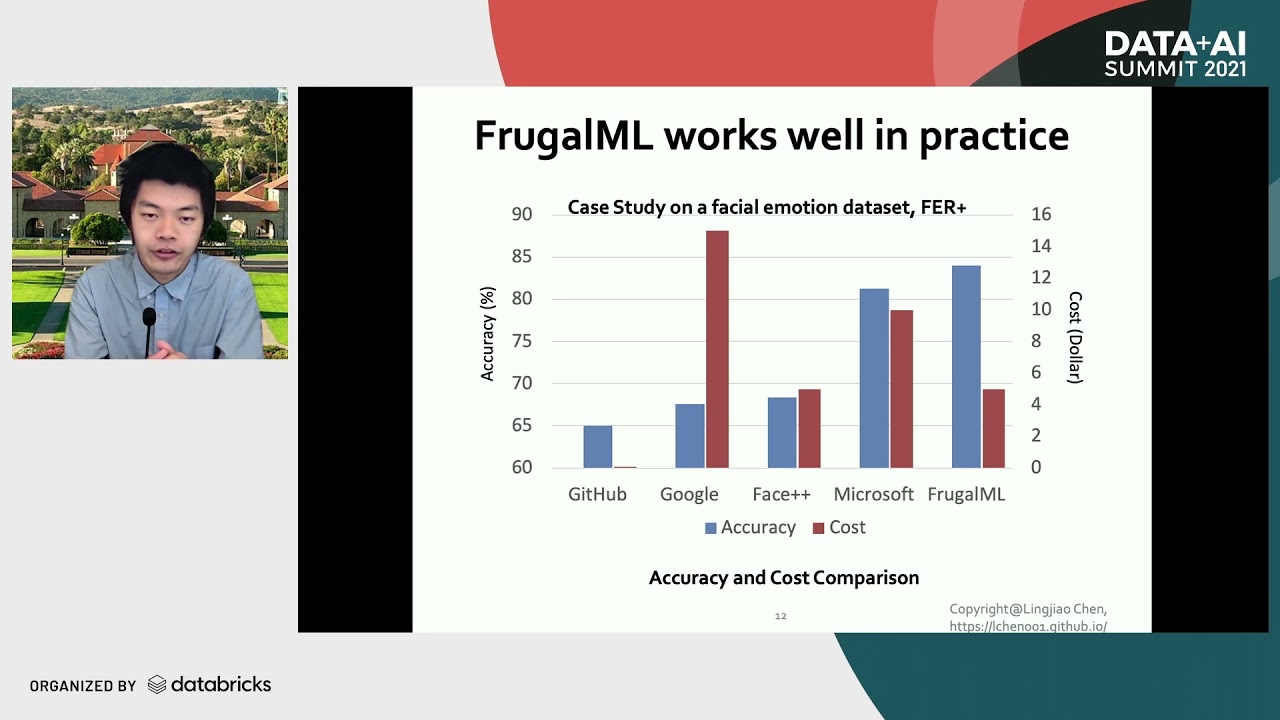
FrugalML: Using ML APIs More Accurately and Cheaply
FrugalML learns where paid ML prediction APIs are strong or weak and picks the best sequential strategy for using them within a budget. Experiments with APIs from Google, Microsoft, Amazon and others show up to 90% lower cost at the best single API's accuracy, or up to 5% better accuracy at its cost.
Get Tuesday's version of this
Tracking Cost Optimization? The Tuesday email carries what moved across the whole ecosystem, not just this topic. Free, one-click unsubscribe.