Photon
Recent items mentioning Photon across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Photon enabled but a large share of the plan is falling back, cost up and runtime flat
Does enabling Photon improve performance while lowering compute costs?
Does Photon support CSV?
Ok so I know that the docs state that CSV is supported. But when trying to read a very standard CSV file I get poorer than expected performance and in the Spark UI I see that it's not using a Photon scan operator, just regular Scan CSV followed by a Row to Columnar conversion operator. https://preview.redd.it/1amu93oqqslh1.png?width=260&format=png&auto=webp&s=4ca1c1ffec6cb6f6cd484b4645b0b5d7c5f6be86 I'm not running anything complex: df = ( spark.read .format("csv") .option("header", "true") .schema(schema) .load(csv_path) ) df.write.mode("overwrite").saveAsTable("...") I also checked reading the same CSV and a difference CSV via DB SQL (using `COPY INTO`) and see low task time spent in Photon + a row to columnar operator. https://preview.redd.it/g1tlotk8rslh1.png?width=940&format=png&auto=webp&s=f3d2b22ebab4f716c5b6831d96305c082e1126a8 DBR 19 + Serverless SQL Warehouse (current) Can anyone explain whether or not CSV is supported and in what conditions? This was quite a surprising find as I assumed that Photon supported pretty much everything. submitted by /u/Common_Jaguar474 [link] [comments]
Detecting Photon fallback in-cluster + safe right-sizing from system tables
Most Databricks performance problems don’t start with code — they start with the wrong cluster setup.
I just published a practical guide on Databricks Clusters covering what actually matters in production: • All-Purpose vs Job Clusters • Cluster Pools for faster startup • Cluster Policies for governance • Photon for faster SQL + Delta performance • Spot Instances for serious cost savings • Autoscaling + Auto-termination best practices A lot of teams spend weeks optimizing queries while ignoring the real issue: poor cluster architecture. Sometimes the biggest performance gain is just choosing the right cluster strategy. Wrote this to simplify the concepts and make them useful for real production workloads. Would love to know how your team handles cluster optimization. Medium Blog - [https://medium.com/@wnccpdfvz/everything-you-need-to-know-about-databricks-clusters-production-ready-guide-c5e5ebe90757](https://medium.com/@wnccpdfvz/everything-you-need-to-know-about-databricks-clusters-production-ready-guide-c5e5ebe90757)
 Tutorials
Master Databricks 2nd Ed: Lesson 3 - Understanding Clusters
This video explains Databricks clusters, detailing their components like driver and worker nodes, configuration options such as autoscaling and Photon acceleration, and how to create and manage them within Azure. It also covers common interview questions related to cluster sizing and performance tuning, emphasizing that Databricks clusters are essentially Spark clusters enhanced with the Databricks runtime for cloud environments.
 Tutorials
Top Performance and Cost Optimizations for DLT
Performance optimization for DLT involves identifying CPU, memory, and IO bottlenecks and adjusting instance types, partition sizes, and autoscaling strategies to balance cost and speed. Databricks offers built-in optimizations like liquid clustering, Photon vectorized execution, microbatch pipelining, and Enzyme to reduce workload latency and cost automatically.
 News
Transforming Data Pipeline Management With a Targeted Proof of Concept
Capital One's credit line increase program required processing trillions of records across 160 customer behavior and financial features using data from multiple sources, but their existing compute infrastructure was timing out. By migrating to Databricks' Photon processing engine, they achieved an 80% reduction in time and cost per job, completing operations 60 times faster.
 News
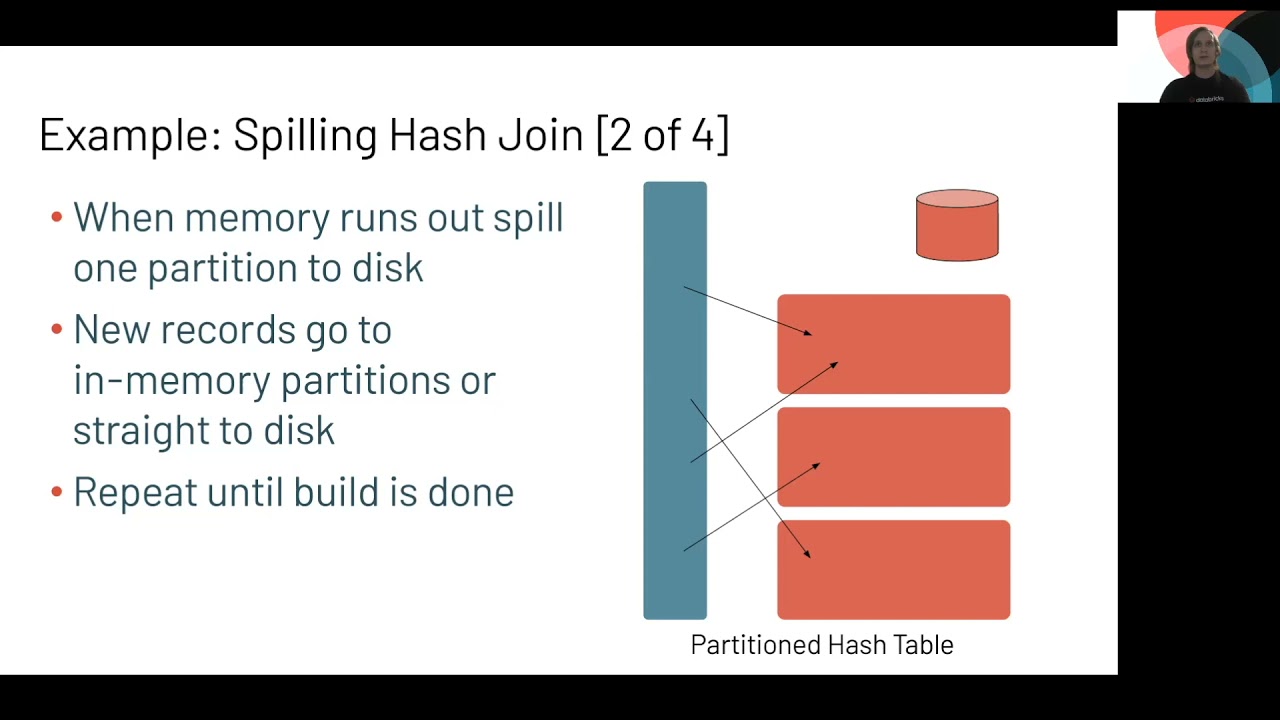
Understanding Databricks & Apache Spark Performance Tuning: Lesson 02 - Spark Hardware
 News
Databricks and Delta Lake: Lessons Learned from Building Akamai's Web Security Analytics Product


 News
How AT&T Data Science Team Solved an Insurmountable Big Data Challenge on Databricks


Get Tuesday's version of this
Tracking Photon? The Tuesday email carries what moved across the whole ecosystem, not just this topic. Free, one-click unsubscribe.