
43 Lakehouse Federation or Query Federation in Databricks | Query External Database |Foreign Catalog
Summary
Lakehouse Federation in Databricks allows querying external databases like PostgreSQL directly without importing data, using connections and foreign catalogs with Unity Catalog governance and lineage support. The demo shows setting up a PostgreSQL connection, creating a foreign catalog, and executing federated SQL queries that join external tables.
Summary generated by brickster.ai from the video transcript.
Topics
More from Ease With Data
 News
What are Agents & How they Work? #agent #llm #genai
AI agents combine a large language model for reasoning, external digital tools for executing actions, and memory for tracking context to complete complex tasks autonomously. This architecture allows the system to continuously loop through planning, executing, and adjusting steps until a defined goal, such as organizing a chaotic folder of files, is fully achieved.
 News
Forward Deployed Engineers (FDE) vs Data Engineers (DE) #fde #dataengineering
Forward deployed engineers embed with business executives to build custom AI models that solve specific problems like customer churn directly within legacy systems, contrasting with traditional data engineers who maintain data infrastructure and pipelines. They command premium salaries because they combine production-level coding skills with management consulting expertise to implement solutions without disruptive migrations.
 Tutorials
Databricks All Purpose vs Serverless Computes #databricks #databrickstutorial
Databricks all-purpose compute provides traditional persistent clusters with manual configuration and continuous uptime costs. Serverless compute offers fully managed infrastructure that boots in seconds, scales dynamically, and bills only for active execution time.
 Tutorials
LangChain Tutorial - Build an AI Agent with Tools | Chapter 10
This video teaches how to build AI agents using the LangChain framework in Python. It demonstrates initializing a model, registering Python functions as structured tools, and creating both single agents and supervisor-sub-agent architectures.
 News
Spark vs SDP, What the difference? #spark #pyspark #dlt
Traditional Apache Spark requires developers to manually write complex procedural code for processing steps, state management, and checkpoints. Spark declarative pipelines allow users to define the desired final data state in SQL or Python while the engine automatically handles execution order, dependencies, and incremental processing.
 News
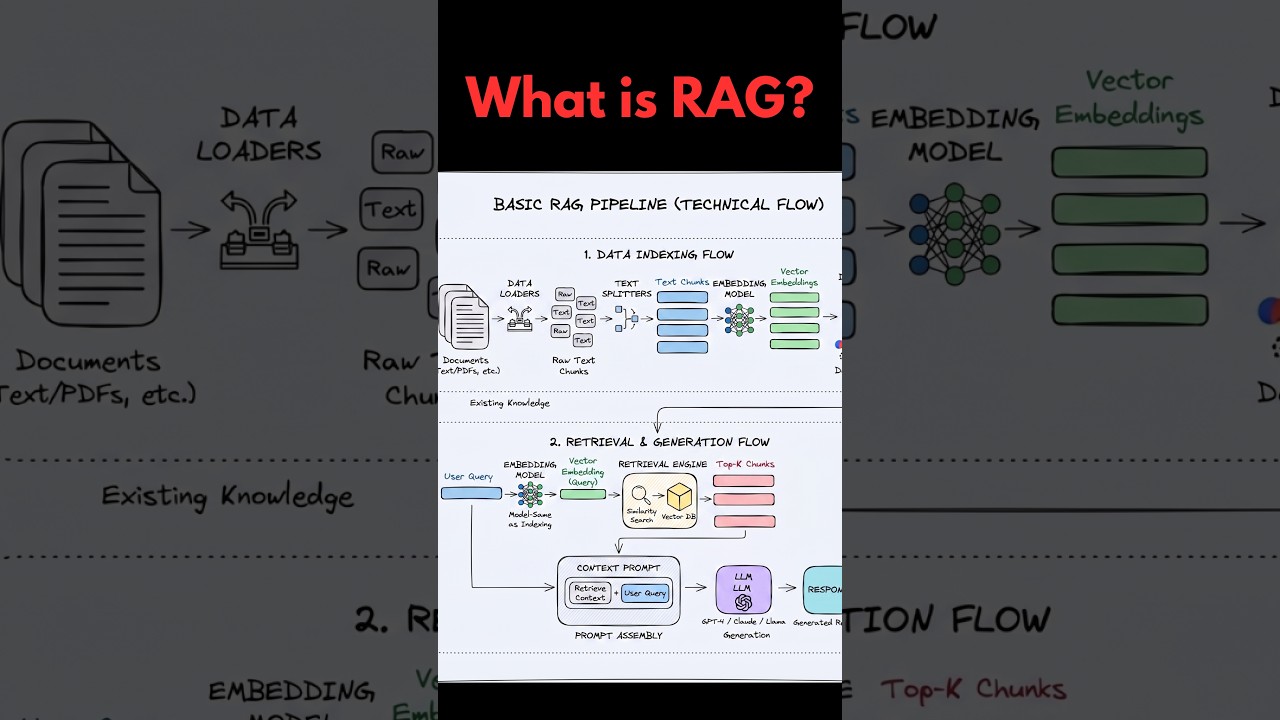
What is RAG and How it Works? #genai #llm #generativeai #coding
RAG solves AI hallucination by chunking large private documents into searchable segments and retrieving relevant context for each user query. The system then augments the user's question with the retrieved context before sending it to the AI, enabling factually accurate answers without guessing.