Kubernetes
Recent items mentioning Kubernetes across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Databricks' AI SRE now triages over 2,000 daily investigations across 1,500 Kubernetes clusters spanning 70+ regions and three clouds 3. Meanwhile, practitioners are actively migrating workloads from Databricks Jobs to Kubernetes-based Spark jobs 1.
Generated daily from the 3 most recent items mentioning Kubernetes. Click any [N] to jump to the source.
Databricks Jobs to Kubernetes Spark Jobs migration
I'm discussing some architectural changes with my data team, and one of them is about cutting costs. The idea is to migrate Databricks Jobs to Spark jobs on Kubernetes. We've done a PoC and it works well. But despite the clear cost savings, I'm getting pushback from management and they're resisting the change. Can someone explain the reason behind this? It seems clear that you pay double for running jobs in Databricks, and you could save a lot of money. Yes, doing this means we bypass Unity Catalog, but we could convert only the Bronze and Silver layers. submitted by /u/worldpwn [link] [comments]
MLflow 3.16.0
MLflow 3.16.0 makes the redesigned trace explorer the default interface, introducing natural-language custom trace views via the MLflow Assistant, session grouping for multi-turn conversations, and span links. The update also adds Unity Catalog model service support for built-in evaluation judges, per-user AI Gateway budget policies, and fail-closed authorization by default.
Data Engineers, what does your actual day-to-day work look like? And what should I learn next?
I’m currently trying to transition deeper into Data Engineering and would really appreciate some perspective from people who are already working in the field. I have 1.3 yrs experience as a Junior Python Developer. What I want to do is slowly transform into a Data Engineer. How would you suggest my choice? Basically what I do is make web scraping scripts to get the data from web and give the data in excels. Our company is currently not using git or CI/CD or anything like that. The problem I’m running into is that when I look at Data Engineering jobs on Naukri, LinkedIn, etc., the requirements seem endless. One job asks for Python, SQL, Airflow and AWS; another wants Spark, Kafka and Databricks; another wants Snowflake, dbt, Terraform, Kubernetes, CI/CD, etc. It becomes difficult to understand what I should actually prioritize. So I’d like to hear from people who are actually working as Data Engineers . What does your day-to-day work look like? What kind of problems do you solve, what technologies do you use regularly, and which skills have turned out to be genuinely important in your job? More importantly, based on my current experience, what would you suggest I improve or learn next to become a stronger candidate for Data Engineering roles? Are there any gaps that you think I should focus on, or technologies/concepts that are worth learning through projects rather than just studying theoretically? I’m not really looking for a generic “learn SQL → Python → Spark → AWS” roadmap. I’m more interested in understanding the reality of the job and getting advice from people who have actually gone through the transition. If you’re a Data Engineer with 1–5+ years of experience , I’d especially appreciate your perspective. Even a short description of what you work on and what you wish you had learned earlier would be extremely helpful. Thanks in advance! submitted by /u/Stunning-Space8032 [link] [comments]
How Databricks Uses AI to Accelerate Incident Investigation
Databricks' AI SRE now handles over 2,000 daily investigations across 150+ teams, helping engineers troubleshoot 100s of microservices spread across 1,500 Kubernetes clusters in 70+ regions and three clouds. Rather than relying on black-box reasoning, the system uses composable agentic runbooks and ties every diagnostic recommendation to verifiable raw evidence, embedding a context-first approach into its design.
MLflow 3.15.0 introduces an MCP Registry for registering and sharing Model Context Protocol servers, enhances the Assistant with multi-provider LLM support and per-session token usage tracking, and enables proxy-less artifact transfers via presigned URLs to reduce server load and timeouts on large files. Additional improvements include sharable Runs table views, multi-modal image attachments for LLM judges to evaluate vision tasks, and numerous bug fixes across tracing, evaluation, gateway, and UI components.
Show HN: Ingestr CDC – open-source CDC replication in Go
Hi all, this is Burak, one of the founders at Bruin. I created ingestr to make data ingestion easy. ingestr is a CLI tool that can ingest data from 130+ sources. I have shared it on HN after our Go rewrite as well, which made it the fastest ingestion tool in the space. However, ingestr had always been a batch tool. I am personally a big fan of batch workloads due to their simplicity and have built ingestr around that assumption as well; however, over time, the cracks started to show when we started working with larger orgs. Turns out there are some scenarios where CDC proves beneficial: - For legacy systems where it is not possible to introduce cursor columns due to technical, but mostly organizational, concerns, it becomes impractical to deploy batch pipelines. - For systems that do not have a way to reliably know the update timestamp, also due to legacy reasons. Think usecases where the columns are updated without the timestamp being updated. - For hard deletes. Even though I do believe there are ways to solve each of these, it ended up putting us in a disadvantage, and we decided to build the CDC connectors instead. ingestr CDC works in two modes now: batch (bad name, I know) and stream. The batch mode is reading the changelog entries from the last load until the starting timestamp, and the streaming mode keeps reading and landing them to the destination databases. ingestr has a few advantages compared to a more traditional debezium + kafka setup: - it's a standalone Go binary and does not require any additional infra. - it has very low resource consumption, ~100MB baseline. - it can run on your own computer during development, and can be converted into a streaming prod deployment when it is ready. - supports 20+ destinations already, primarily analytical platforms like snowflake, databricks, generic iceberg destinations, etc. i would love to hear any feedback on what we could do to make it easier for cdc workloads! https://github.com/bruin-data/ingestr --- top comments --- [mercutio93] Man I have had a lot of gripes with debezium... the setup alone in a kubernetes cluster with strimzi kafka connect... And dealing with the kafka connect errors and fixing replication slots... ehhh was painful. Does this tool make it any well easier. One problem I expirienced in production systems with staging doubles is that sometimes we do database restores from production onto staging and that makes the sinks and sources go haywire... does ingestr handle this well? Is support for kubernetes/helm anywhere in the pipeline
Can Databricks Jobs Run on Kubernetes Clusters?
MLflow 3.13.0 introduces Role-Based Access Control with Admin UI, automatic trace archival to S3, and one-click observability for Claude Code and other coding agents. Breaking changes include a redesigned permission system (legacy APIs removed), MLServer removal from pyfunc serving, and requirement for MLFLOW_ALLOW_FILE_STORE=true flag for local file-based stores.
MLflow 3.13.0rc0 completely overhauls Role-Based Access Control with unified permission APIs and a new Admin UI, and integrates Claude Code, OpenAI, Ollama, and OpenClaw as native assistant providers in the AI Gateway. The release adds trace archival with seamless retrieval, GenAI agent stress-testing, Kubernetes Helm chart support, and database replica routing for horizontal scaling.
Show HN: Recursant – service mesh for governing AI agents
Hello, I have just released Recursant to the public. I have been working on it for a while. It is a control plane for governing AI agents across stacks. It provides full observability, guardrails, and control on the network level by routing all traffic through a side car. Problem statement: many large, regulated enterprises (think banks, telcos) have one engineering team on LangGraph, another on CrewAI, marketing on AgentForce, and data teams on Databricks Agent Bricks. They need their agents to talk to each other with consistent policy enforcement, one audit trail, and a single set of guardrails, yet allowing different functions to run on their own stacks. Recursant solves that problem using the service mesh pattern Recursant has two components: a registry and the mesh . The registry contains all live agents. The mesh uses sidecars to route traffic and enforce on the network layer. Aim is for Recursant to provide a real-time EU AI Act Annex IV compliance, so it is not generated from static documents. This saves time and effort for large enterprises subject to the requirement. Linmitations: - Recursant currently plugs in to CrewAI, Langgraph, and n8n . The aim is to support proprietary platforms such as ServiceNow and AgentForce as much as psosible. - The Recursant SDK still needs work to support as many agents as possible - I would also like to provide support for some of the 'personal agent' platforms such as OpenClaw, NanoClaw, and Hermes - Only tested on k8s, not public cloud - Documentation is sparse and needs to be developed. I hope this project is useful to some of you. --- top comments --- [goodra7174] clawdlinux.org building the Kubernetes-native runtime that AI agents call to provision their own secure execution environments — the missing infrastructure layer for every enterprise that can’t send agent data to the cloud #Ycombinator #buildinpublic #startups
MLflow 3.11.1 introduces AI-powered issue detection in traces, AI Gateway budget alerts and spending controls, trace graph visualization, native Databricks gateway provider, and pickle-free model serialization. TypeScript SDK packages are now @mlflow-scoped and LiteLLM is no longer required for GenAI evaluation.
UnityCatalog 0.3.0
UnityCatalog 0.3.0 adds support for Spark 4.0 and Delta 4.0 with new credentials and external locations APIs enabling flexible external storage management. The release includes Kubernetes deployment via Helm charts and fixes for Delta time-travel SQL queries.
 News
Saving Millions From Millions: Navigating Towards Cost-Efficiency in Pinterest's Spark Jobs
Pinterest built a three-layer cost optimization system for Spark jobs using observability platforms (collecting real-time metrics and event logs), platform innovations (Apache Celeborn remote shuffle service and Kubernetes burst-aware memory allocation), and fine-grained management tools. Production deployments achieved 30-50% cost reductions per job through resource tuning while improving cluster utilization.


 Releases
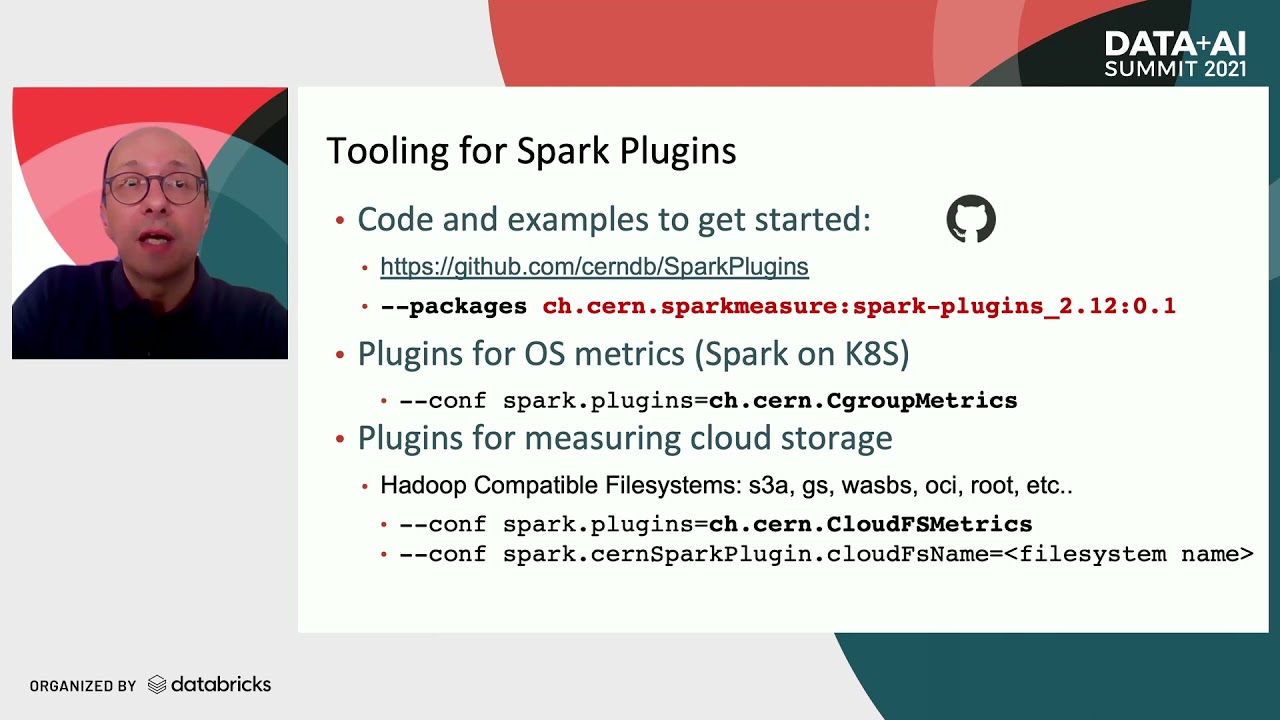
Apache Spark on Kubernetes—Lessons Learned from Launching Millions of Spark Executors







Get Tuesday's version of this
Tracking Kubernetes? The Tuesday email carries what moved across the whole ecosystem, not just this topic. Free, one-click unsubscribe.