
Description
The abundance of data as well as regulations protecting people’s privacy created a need for protecting private and personal information in a scalable and efficient way. Personal data includes sensitive and private information such as health records, banking transactions and frequent locations. One of the challenges of data anonymization is when the data anonymity increases its usefulness for analytics or research decreases. This paper provides an implementation of Top-Down Specialization algorithm for data anonymization in parallel using Apache Spark which aims to balance data utility and data privacy. Performance evaluation is done on large datasets of up to 20-million rows in a variety of different cluster environments. The talk analyzes the different speedups achieved using different data sizes. It also discusses changes made to the algorithm to improve performance such as determining partitions size, determining what should run on the driver and what should run on the executor as well as scale-up experiments of the algorithm. Web page for the topic proposed including slides, code as well as the research paper I wrote is here: micophilip.github.io/comp5704/ About: Databricks pr…
Description from YouTube. Full content on the video page.
More from Databricks
 News
Parallel Coding Agents with Lakebase | Claude Code + GitHub Actions
This video demonstrates how to run multiple coding agents in parallel by combining git worktrees, GitHub Actions, and Lakebase database branching. It shows how each agent automatically receives an isolated database branch for safe experimentation and schema migrations, followed by dedicated preview environments for pull requests.
 Events
How Enterprises Govern AI Agents Across Multiple Models
Databricks announced the general availability of the Unity AI gateway to provide centralized multi-model governance, cost controls, and end-to-end observability for enterprise AI agents. Panelists discussed how coding agents and harnesses are evolving beyond programming into long-running operations, personal software development, and automated organizational workflows.
 Events
Demo: Building a Governed AI Agent with Unity AI Gateway
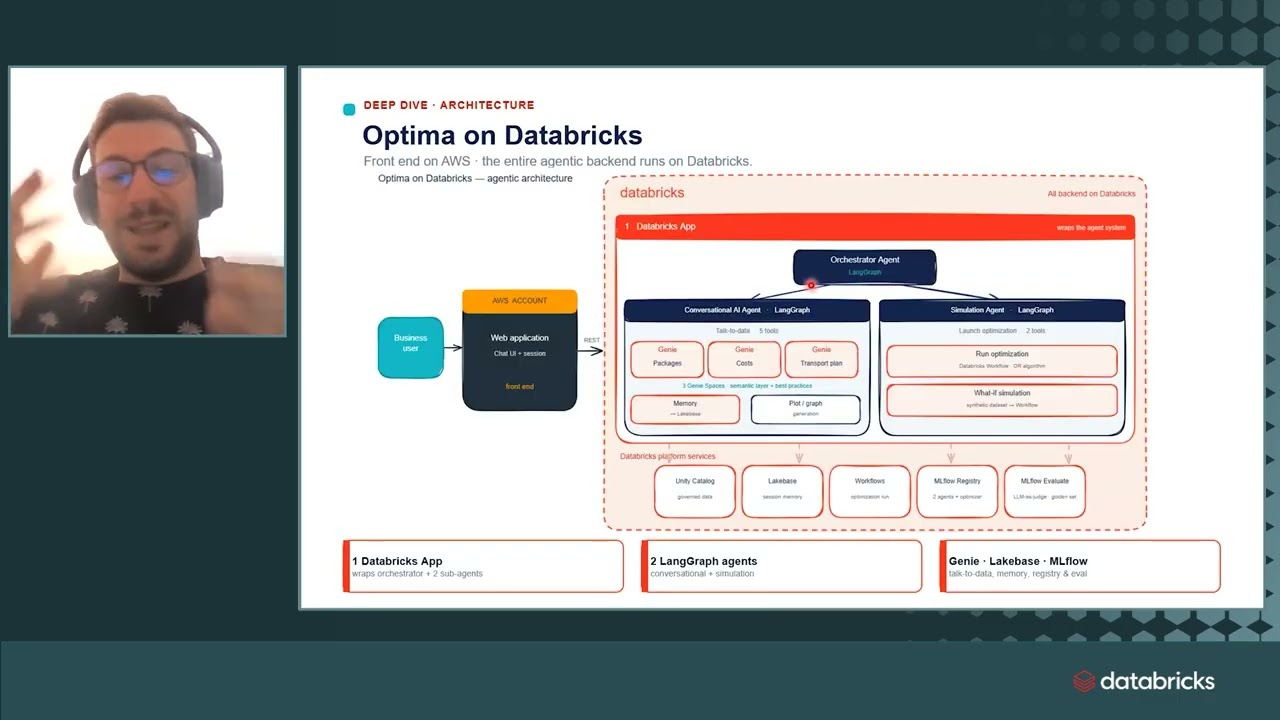
This video demonstrates how to build, update, and govern a store operations AI agent using Databricks Agent Bricks and the Unity AI Gateway. The tutorial highlights integrating custom Model Context Protocol servers, recording execution traces with MLflow, and enforcing security policies and budget controls.
 News
How ModMed Transforms Healthcare AI and Agentic Workflows with Databricks
ModMed uses the Databricks Lakehouse platform and Unity Catalog to build secure AI-enabled healthcare applications and agentic workflows. The integration of these tools allows both technical and non-technical users to access near real-time data insights and solve complex problems efficiently.
 News
Teach AI how your business actually runs
Model intelligence is no longer the bottleneck for enterprise AI adoption because modern frontier models easily handle complex reasoning tasks. Business value requires providing these models with specific organizational context and metadata about internal processes to create a competitive advantage.